Database > RDS for MariaDB > DB Instance
DB Instance
DB instance is a concept that encompasses virtual equipment and installed MariaDB, a unit of MariaDB provided by RDS for MariaDB. You do not have direct access to the operating system of the DB instance, but only to the database through the port you entered when you created the DB instance. The available port ranges have the following restrictions. The available port range is between 3306 and 43306.
The DB instance is identified by the customer-assigned name and the automatically assigned 32-byte ID. DB instance name has the following restrictions.
- DB instance name must be unique by region.
- DB instance name contains alphabets, numbers, and - _ between 1 and 100 characters. ,and the first character must be an alphabet.
Note
After the maintenance in July 2025, for high-availability DB instances, the name of the Standby must be entered in addition to the Primary. The Standby name follows the same restrictions as the Primary name, and the two names must be different. For DB instances created before this maintenance, the Standby name is the same as the Primary.
Create DB Instance
You can create DB instance with the following settings.
Availability Zone
NHN Cloud has divided the entire system into several availability zones to prepare for failures caused by physical hardware problems. These availability zones are storage systems, network switches, top surfaces, and power supplies, which are all configured separately for each zone. Failure within one availability zone does not affect other availability zones, increasing the availability of the entire service. Deploying DB instances across multiple availability zones can further increase the service availability. Network communication is possible between DB instances that are scattered across multiple availability zones, and there is no network usage charge.
Caution
You cannot change the availability zone of DB instance that you have already created.
DB Engine
The versions specified below are available. New DB instance creation and Read Replica additions are supported only for the seven most recent minor versions of each major version.
| Version | Note |
|---|---|
| 11.8 | |
| MariaDB 11.8.8 | |
| MariaDB 11.8.6 | |
| 11.4 | |
| MariaDB 11.4.14 | |
| MariaDB 11.4.10 | |
| MariaDB 11.4.7 | |
| 10.11 | |
| MariaDB 10.11.18 | |
| MariaDB 10.11.16 | |
| MariaDB 10.11.13 | |
| MariaDB 10.11.8 | |
| MariaDB 10.11.7 | |
| 10.6 | |
| MariaDB 10.6.25 | Creation and Read Replicas unsupported |
| MariaDB 10.6.22 | Creation and Read Replicas unsupported |
| MariaDB 10.6.16 | Creation and Read Replicas unsupported |
| MariaDB 10.6.12 | Creation and Read Replicas unsupported |
| MariaDB 10.6.11 | Creation and Read Replicas unsupported |
| 10.3 | |
| MariaDB 10.3.30 | Creation and Read Replicas unsupported |
Details about DB engine can be found in DB Engine.
DB Instance Type
DB instances have different CPU cores and memory capacity depending on the type. When creating a DB instance, you must select an appropriate DB instance type according to the database workload.
| Type | Description |
|---|---|
| m2 | Instance type that balances CPU and memory. |
| c2 | Instance type with high CPU performance. |
| r2 | Available when memory is busy compared to other resources. |
| x1 | Instance type that supports higher-end CPU and memory. Recommended for services or applications that require high performance. |
The type of DB instance that you have already created can be easily changed through the console.
Caution
If you change the type of DB instance that you have already created, the DB instance will be terminated, causing a service downtime of several minutes.
Data Storage
It stores the database's data files in data storage. DB instances support two types of data storage: HDD and SSD. Performance and price vary depending on the type of data storage, so you need to choose the right type depending on the database workload. Data storage can range from 20GB to 2TB.
Caution
You cannot change the data storage type for DB instance that you have already created.
Note
To use more than 2TB of data storage, contact NHN Cloud Customer Support.
Because the following tasks increase the I/O usage of data storage, the performance of DB instance may be degraded during the process.
- Back up single DB instance
- Configuring High Availability for single DB Instance
- Create Read Replica
- Rebuild Read Replica
- Rebuild Standby
- Restore to a certain point in time
- Export backup files to Object Storage after backing up from a single DB instance
High Availability
High availability DB instances increase availability, data durability, and provide fault tolerant databases. High availability DB instances consist of Primary and Standby and are created in different availability zones. Standby is a DB instance for failover and is not normally available. For high availability DB instances, backups are performed on Standby, which avoids performance degradation caused by backups. Several features provided by a high availability DB instance can be found in High Availability DB Instance.
Network
When create DB instance, you have to select the VPC subnet to connect to. You can communicate without a separate floating IP between instances of Compute service connected to the same subnet and you will not be charged for network traffic. DB instances block all network access by default, so you must apply DB security groups if you want to connect.
Caution
You cannot change the subnet of DB instance that you have already created.
Floating IP
To access DB instance from the outside, you must connect the floating IP to DB instance. You can create a floating IP only if you connect the subnet to which the Internet Gateway is connected. Floating IP is charged upon use, and separately, if traffic is directed to the Internet through floating IP, it is charged separately.
Parameter group
A parameter group is a set of parameters that allow you to set up a database installed on DB instance. You have to select one parameter group when creating a DB instance. You can change parameter groups freely after creating. Refer to Parameter Group for a detailed description of parameter groups.
DB Security Group
DB security groups are used to restrict access in case of external intrusion. You can allow access to specific port ranges or database ports for incoming and outgoing traffic. You can apply multiple DB security groups to DB instance. For more details on DB security groups, see the DB security groups.
Backup
You can set up periodic backups of the databases in your DB instance, or you can create backups at any time through the console. Performance may degrade during backups. To avoid affecting service, it is better to perform back up at a time when the service is under low load. If you do not want the backup to degrade performance, you can use a high-availability configuration, back up only the incremental data since the previous backup, or perform backups from a Read Replica. Backup files are stored on internal backup storage and are charged based on the size of backup storage. You can export to NHN Cloud Object Storage if necessary. To prepare for unexpected failures, we recommend that you set up backups to be conducted periodically. For more details on backup, see Backup and Restore.
Maintenance
The Maintenance feature allows you to schedule various changes to your DB instance at your preferred time. Since tasks such as modifying instances or upgrading the DB engine and operating system require a restart, downtime may occur. By scheduling a maintenance duration, you can ensure these operations occur during periods of low service load.
Maintenance Duration
You can set a maintenance duration when creating or modifying a DB instance. If no duration is specified, a 30-minute slot will be automatically assigned at random between 10 PM and 6 AM. Note that the maintenance duration cannot overlap with the automated backup duration.
Note
A maintenance duration consists of a start day, a start time, and a duration (in 30-minute increments).
Maintenance Task
Maintenance tasks are categorized into User Maintenance and Provider Maintenance.
User Maintenance Task
A task that users manually schedule and execute.
- DB instance modifications (e.g., changing instance specs, port updates, parameter group changes)
- DB engine version upgrade
- DB instance OS upgrade
Provider Maintenance Task
A maintenance task provided by NHN Cloud.
- Apply parameter group changes
- Migration for hypervisor maintenance
Maintenance Execution Time
You can choose when to apply maintenance tasks.
- Apply Immediately: apply immediately upon request.
- Apply in the Next Maintenance Duration: apply during the next maintenance duration.
Maintenance Status
You can check the maintenance status of each instance in the DB instance list.
| Status | Description |
|---|---|
| None | There are no scheduled or pending maintenance tasks. |
| Next Applied | A user maintenance task is scheduled to run in the next maintenance duration. |
| Applying | A maintenance task is in progress. |
| Required | A required provider maintenance task is pending. |
| Available | A non-required provider maintenance task is pending/in preparation. |
Note
The maintenance status is not displayed for the Standby of High Availability (HA) DB instances.
Maintenance Tab
You can find the following information on the Maintenance tab of the DB instance details page:
- Maintenance start day and duration
- Next maintenance duration
- Maintenance status
- Upcoming maintenance tasks (Scheduled for the next duration)
- Pending maintenance tasks
Upcoming maintenance tasks can be excluded from the maintenance duration clicking the Hold or Delete buttons. For pending Provider maintenance tasks, you can manually apply them by selecting either Apply Immediately or Apply in the Next Maintenance Duration.
Execution Order
All tasks within the maintenance duration are executed sequentially in the order they were registered. However, mandatory maintenance tasks that have expired will be prioritized and executed first. Any tasks not completed within the current duration will be rescheduled to the next maintenance duration.
Note
If a maintenance task is repeatedly deferred because the maintenance duration starts while an automated backup is in progress or the DB instance is in a 'Busy' state, that task will be skipped and rescheduled for the next duration. An event will be generated if a maintenance task is skipped.
Default Notification
When you create a DB instance, you can set default notifications. If setting default notifications, it will create a new notification group with the name {DB instance name}-default and will automatically set the notification items below. You can freely modify and delete alert groups that are created as default notifications. For more details on the notification group, see the notification group .
| Item | Comparison Method | Threshold value | Duration |
|---|---|---|---|
| CPU Usage | >= | 80% | 5 minutes |
| Storage Remaining Usage | <= | 5,120MB | 5 minutes |
| Database Connection Status | <= | 0 | 0 minute |
| Storage usage | >= | 95% | 5 minutes |
| Data Storage Defects | <= | 0 | 0 minute |
| Connection Ratio | >= | 85% | 5 minutes |
| Memory Usage | >= | 90% | 5 minutes |
| Slow Query | >= | 60 counts/min | 5 minutes |
Deletion Protection
If you activate deletion protection, you can protect DB instances from accidental deletion.
DB Instance List
You can view DB instances created from the console. It can be viewed as groups of DB instances or as individual DB instances.
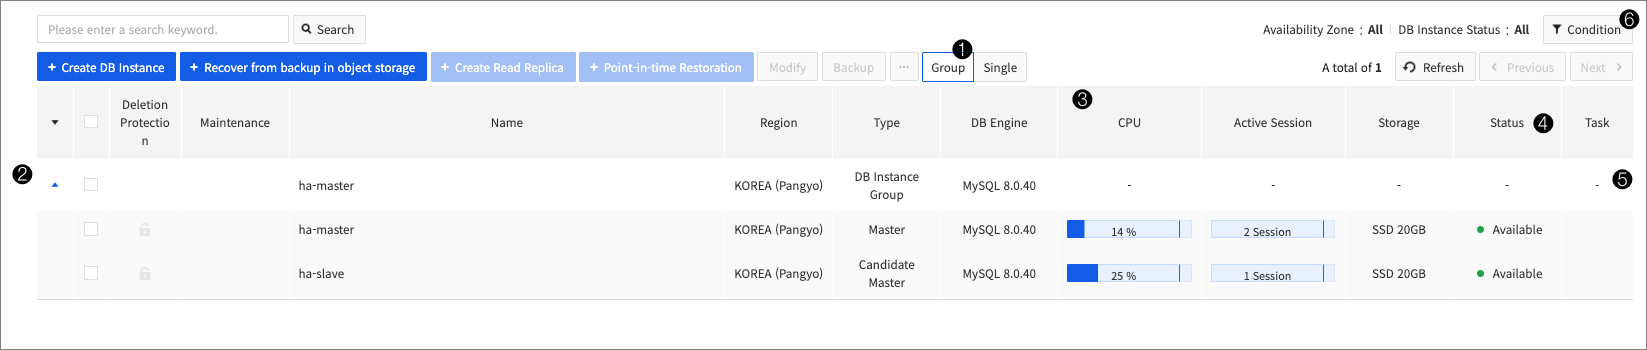
❶ You can change DB instance screen mode.
❷ By clicking on the button, you can open or close a DB instance that belongs to a group.
❸ It displays the most recently collected monitoring indicators.
❹ You can view the current status.
❺ A spinner will appear if have any work in progress.
❻ You can change the search criteria.
The status of the DB instance consists of the following values and changes depending on the behavior of the user and the current status.
| Status | Description |
|---|---|
| BEFORE_CREATE | Before Create |
| AVAILABLE | Available |
| STORAGE_FULL | Insufficient capacity |
| FAIL_TO_CREATE | Failed to create |
| FAIL_TO_CONNECT | Linking failed |
| REPLICATION_STOP | Replication stopped |
| FAILOVER | Failover complete |
| SHUTDOWN | Stopped |
Search conditions that can be changed are as follows.
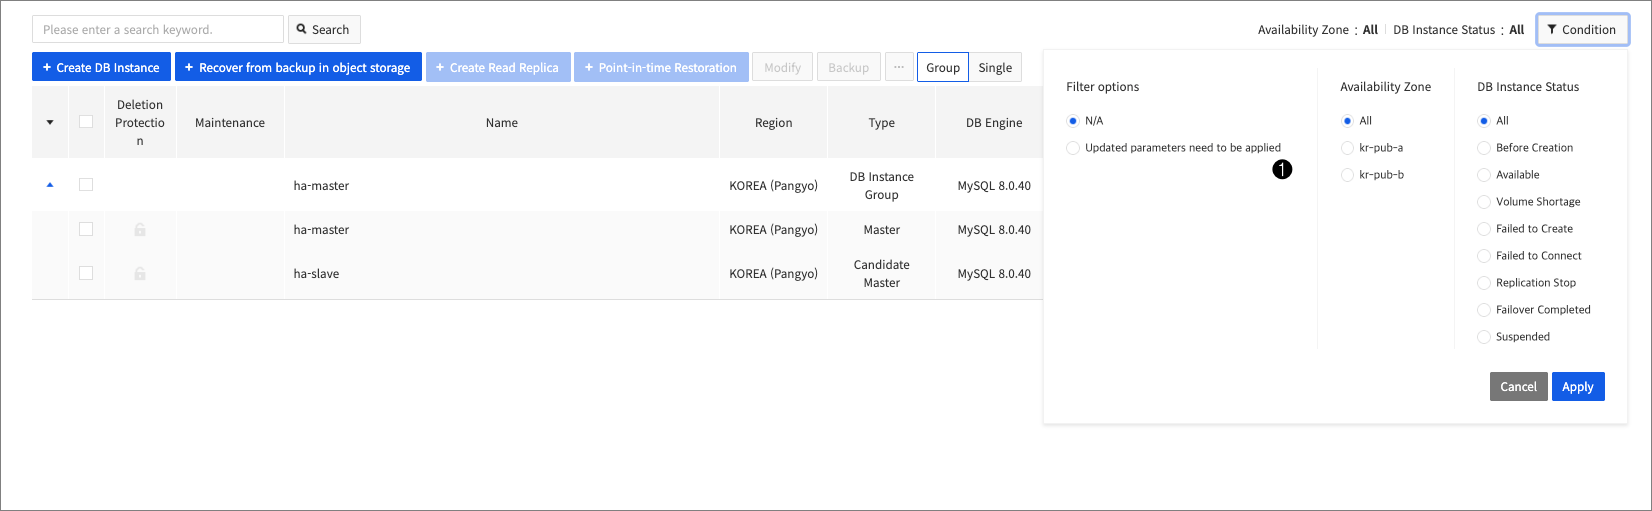
❶ You can search for DB instances with filtering conditions that require parameter changes to be applied.
DB Instance Group Details
After viewing the DB instance list in the Group view, select a DB Instance Group to view its detailed information. The group details screen displays the following tabs:
| Tab | Description |
|---|---|
| Basic Information | Displays the DB Instance Group name and ID, high availability configuration, Primary and Standby names, and Ping settings. |
| DB Schema and Users | Manages the DB schemas and users of DB instances in the group. The DB schema and user features are provided in the DB Instance Group details, not in the individual DB instance details. |
DB Schema and Users
In the DB Schema and Users tab of the DB Instance Group details, you can view and manage the schemas and users of databases that belong to the group.
DB schema created
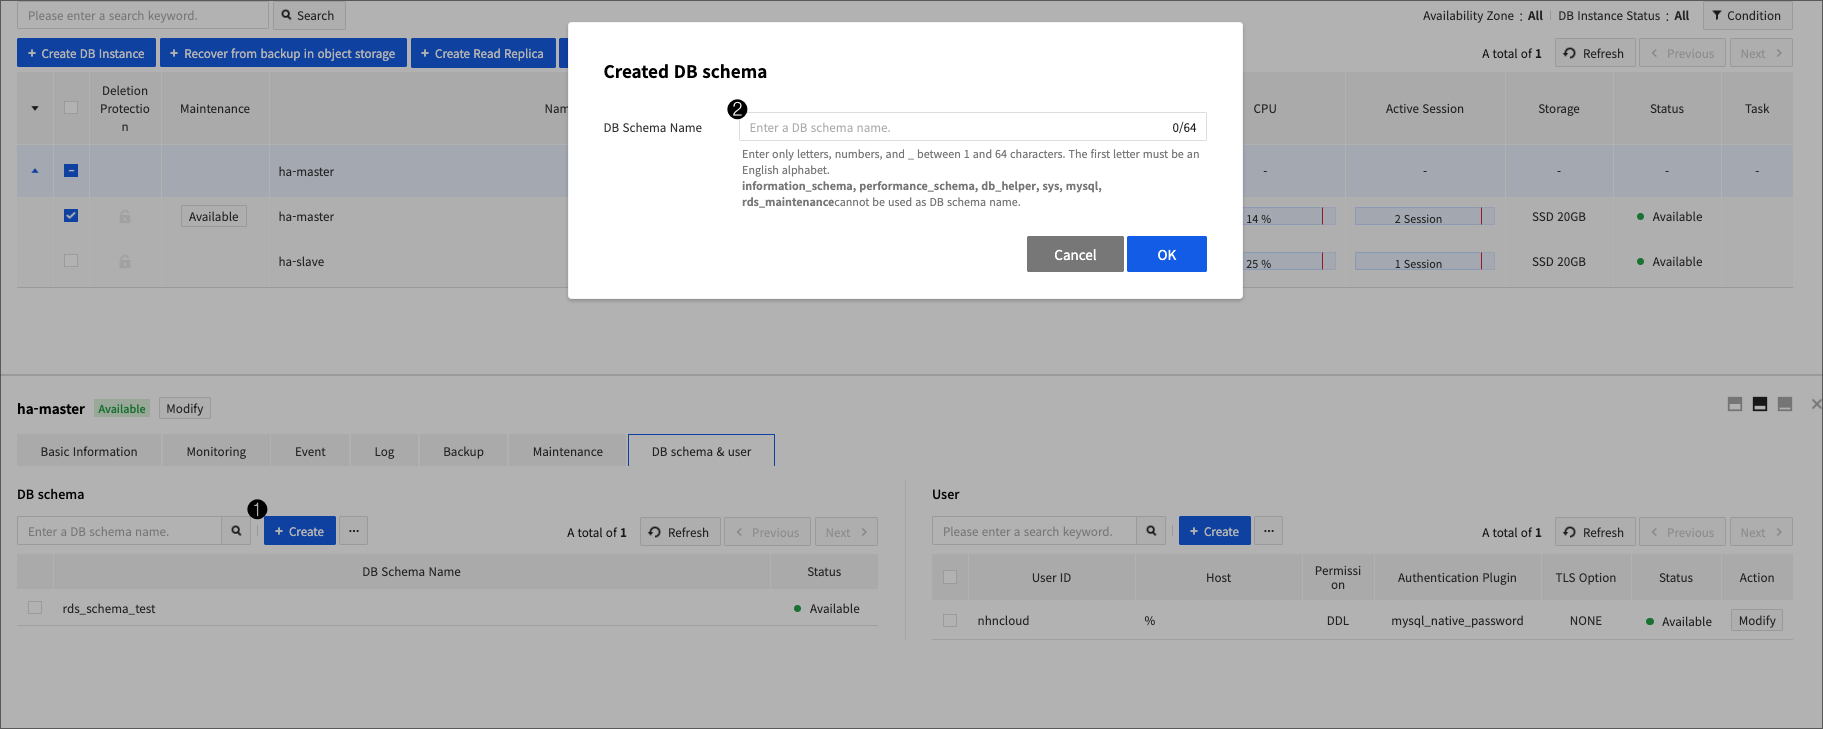
❶ Click on Create and a pop-up window will appear where you can enter the name of DB schema. ❷ You can create a DB schema by entering the DB schema name and clicking on Confirm.
DB schema name has the following restrictions.
- You can only use alphabets, numbers, and _ from 1 to 64 characters and the first letter can only contain alphabetic characters.
information_schema,performance_schema,db_helper,sys,mysql,rds_maintenanceare not allowed to be used as DB schema name.
You cannot modify the name of the DB schema that has been created.
DB schema deleted
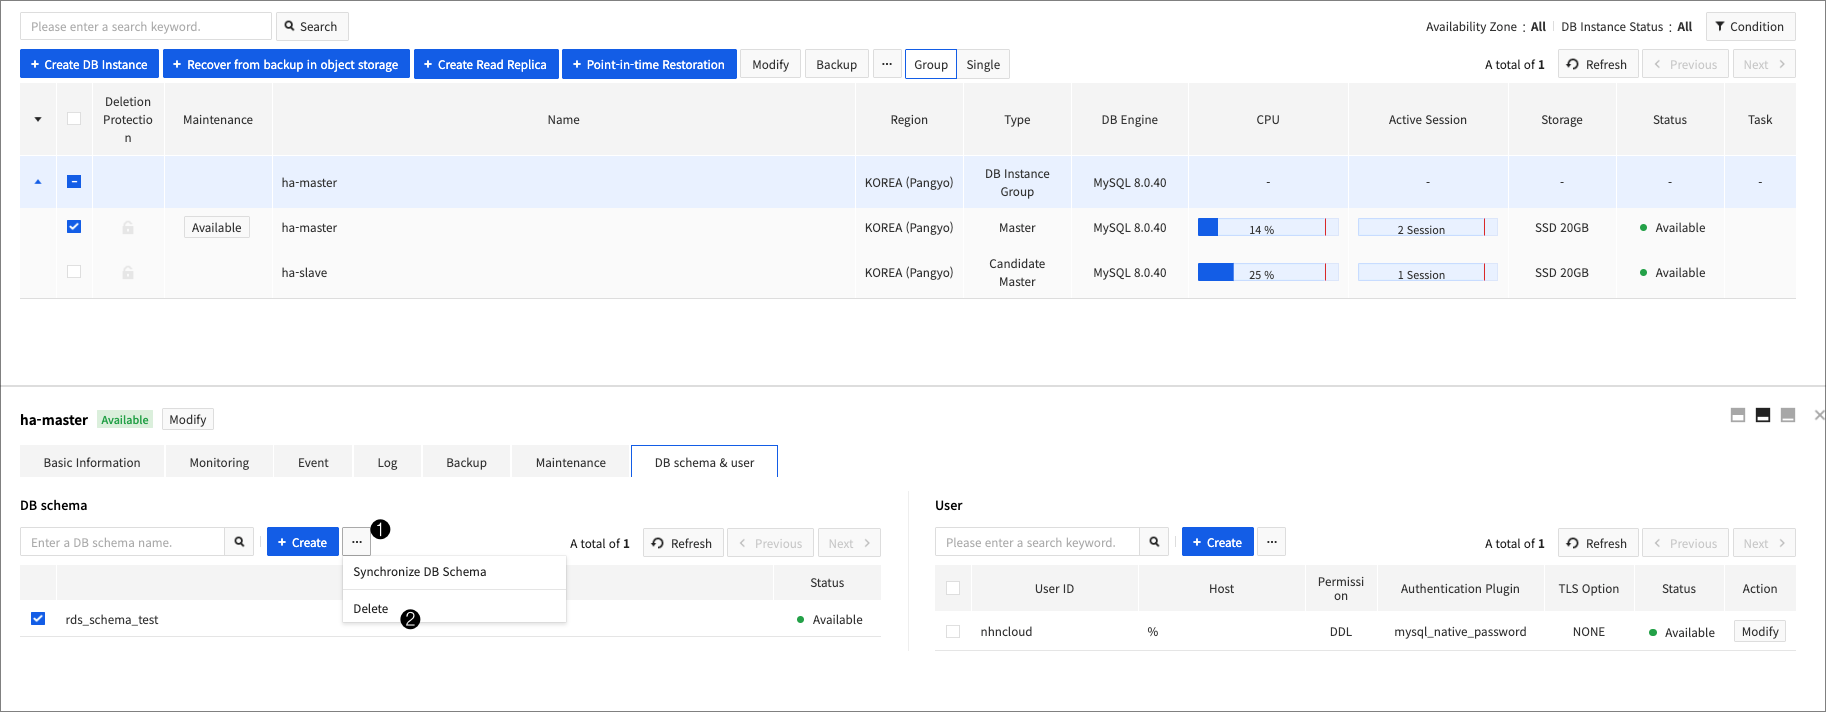
❶ Select DB schema you want to delete and click on the drop-down menu. ❷ Click on Delete menu and pop-up window will appear to confirm deletion. You can request to delete by clicking on Confirm.
Create a user
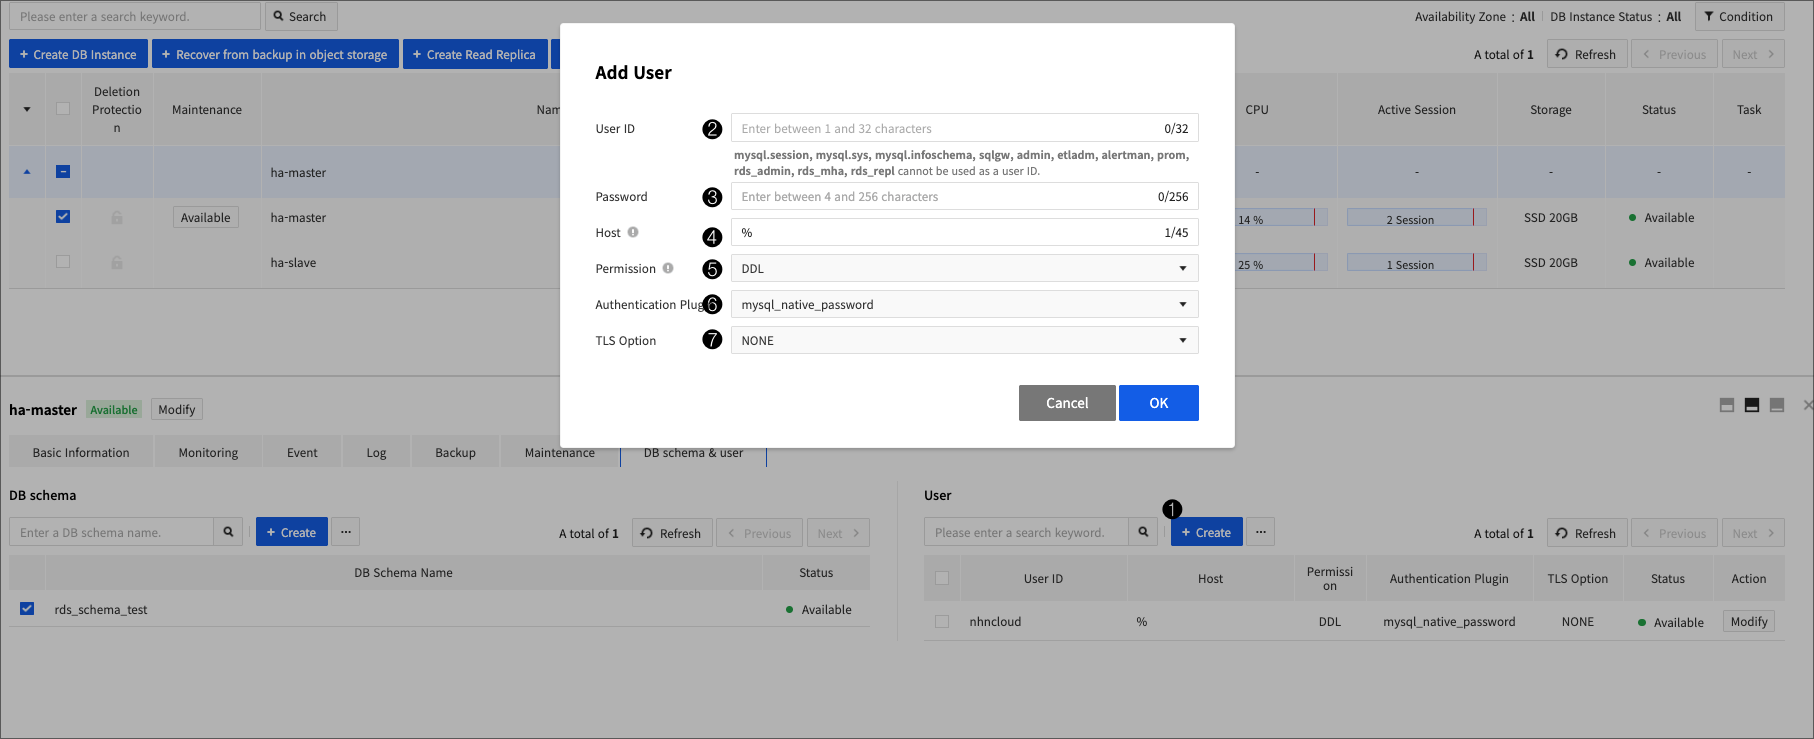
❶ Click on +Create and you'll see the Add User pop-up window. ❷ Enter a user ID.
User ID has the following restrictions.
- It must be between 1 and 32 characters.
mysql.session,mysql.sys,mysql.infoschema,sqlgw,admin,etladm,alertman,prom,rds_admin,rds_mha,rds_replare not allowed to be used as User ID.
❸ Enter a password.
❹ Enter a Host IP to allow connection. Using % character lets you range the Host IPs you want to allow. For example, 1.1.1.% means all IPs between 1.1.1.0 and 1.1.1.255.
❺ Select the permissions that you want to grant to users. The permissions and descriptions that you can grant are as follows.
READ * You have permission to view.
GRANT SELECT, SHOW VIEW, PROCESS, SHOW DATABASES, REPLICATION SLAVE, REPLICATION CLIENT ON *.* TO '{user_id}'@'{host}';
GRANT SELECT ON `mysql`.* TO '{user_id}'@'{host}';
GRANT SELECT, EXECUTE ON `sys`.* TO '{user_id}'@'{host}';
GRANT SELECT ON `performance_schema`.* TO '{user_id}'@'{host}';
CRUD * Includes READ permission, and has permission to modify data.
GRANT INSERT, UPDATE, DELETE, CREATE TEMPORARY TABLES, LOCK TABLES, EXECUTE ON *.* TO '{user_id}'@'{host}';DDL * Includes CRUD permissions and has permissions to execute DDL queries.
GRANT CREATE, DROP, INDEX, ALTER, CREATE VIEW, REFERENCES, EVENT, ALTER ROUTINE, CREATE ROUTINE, TRIGGER, RELOAD ON *.* TO '{user_id}'@'{host}';
GRANT EXECUTE ON `mysql`.* TO '{user_id}'@'{host}';
CUSTOM * When restoring a DB instance from an external database backup, all users that exist in the database are represented with the CUSTOM permission. * You cannot check what permissions are in the CUSTOM permission template. * If you change from one CUSTOM permission template to another permission template, you cannot change back to a CUSTOM permission template.
Edit users
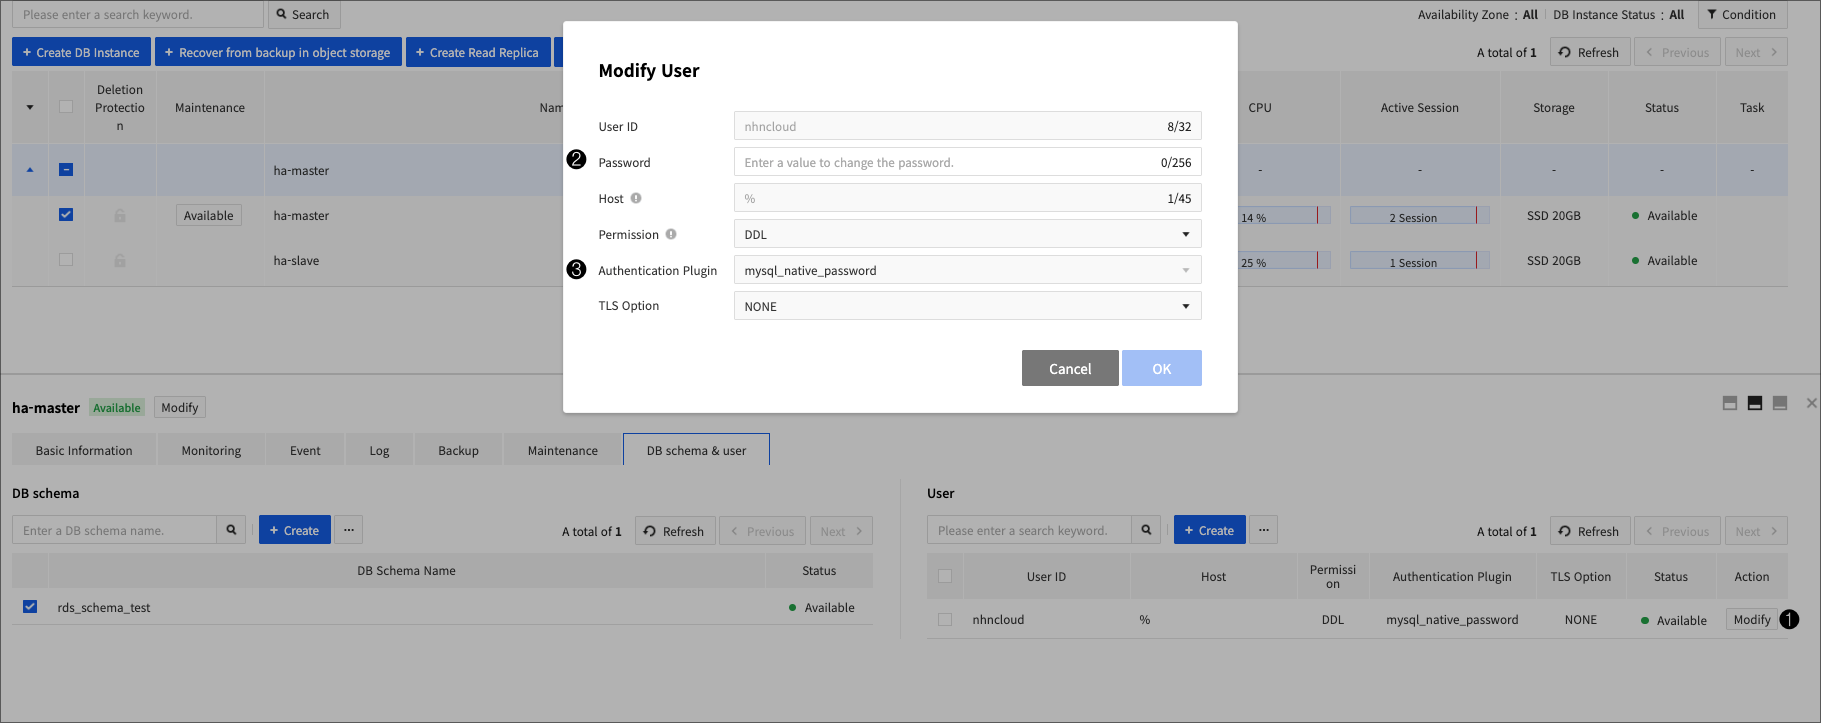
❶ Click on Modify on the user row you want to modify and you will see a pop-up window where you can modify your information. ❷ If you do not enter Password, it will not be changed. ❸ If you want to change the plug-in that applies to user authentication, you must change the password.
Deleting a user
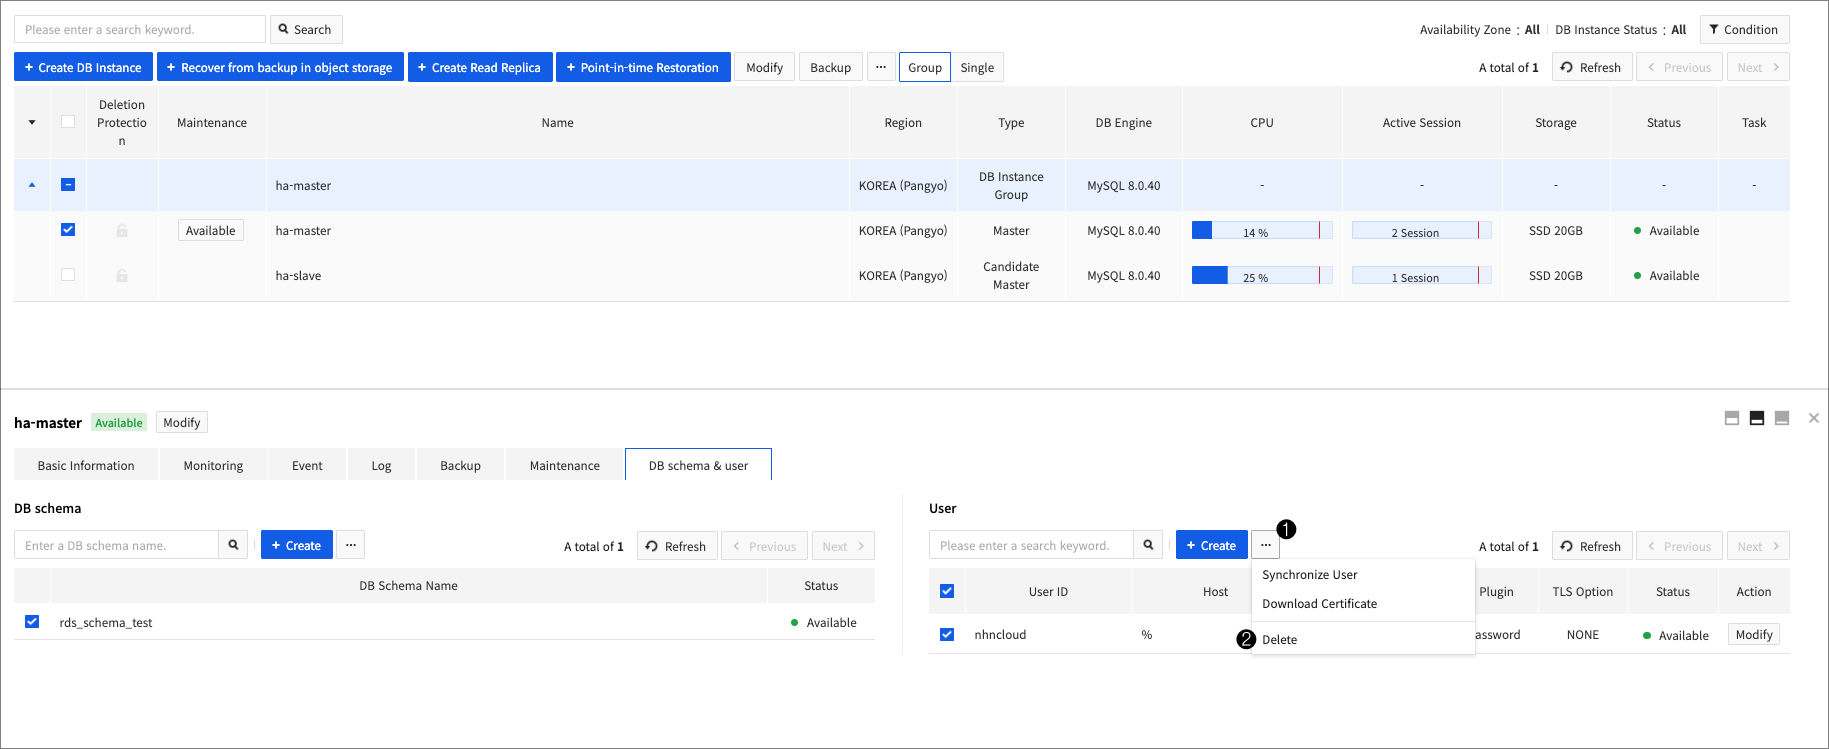
❶ Select the user you want to delete and click on the drop-down menu. ❷ Click on Delete and Confirm Delete pop-up window will appear. You can request deletion by clicking on Confirm.
Update DB Instance Group
On the Basic Information tab of the group details screen, click Modify to change settings at the group level. Change requests are processed asynchronously. You can check the status of the group and the ongoing operations until the changes are complete.
You can change the following items on the modification screen:
| Item | Description |
|---|---|
| DB Instance Group Name | Can contain between 1 and 100 uppercase and lowercase English letters, numbers, -, _, and .. The first character must be an English letter. |
| Primary Name | Managed separately from the group name. |
| High Availability | A standalone configuration can be converted to a high availability configuration, and a high availability configuration can be converted to a standalone configuration. |
| Standby Name | Enter when setting up high availability for the first time. Cannot be the same as the Primary name. The naming rules are the same as for the Primary. |
| Ping Interval | Set within a range of 1 to 600 seconds in a high availability configuration. |
| Ping Method | Select either INSERT or SELECT in a high availability configuration. |
| DB Schema & Direct User Control | Changes whether to use direct control for schemas and users of DB instances in the group. |
Caution
- Disabling high availability deletes the Standby and converts to a standalone configuration. Before proceeding, make sure there is no data or configuration that exists only on the Standby.
- You cannot change the high availability setting for a DB Instance Group while failover is in progress.
- The Primary name cannot be changed in a private network. Also, the Standby name of an existing high availability configuration cannot be changed; the Standby name can only be entered when setting up high availability for the first time.
- In a high availability configuration, the names of the Primary and Standby must be different from each other.
DB Schema & Direct User Control
RDS for MariaDB provides management from the console to make it easier to manage DB schemas and users, but it also provides the feature to set up so that users can control themselves. Direct control grants all currently created users the following privileges.
GRANT CREATE,DROP,LOCK TABLES,REFERENCES,EVENT,ALTER,INDEX,INSERT,SELECT,UPDATE,DELETE,CREATE VIEW,SHOW VIEW,CREATE ROUTINE,ALTER ROUTINE,EXECUTE,CREATE USER,PROCESS,RELOAD,REPLICATION SLAVE,REPLICATION CLIENT,SHOW DATABASES, CREATE TEMPORARY TABLES,TRIGGER ON *.* TO '{user_id}'@'{host}' WITH GRANT OPTION;Caution
If you change it to Disabled again after using direct control * Already granted permissions are not revoked. If you use the command to add DB schema or users at this time, the data in the console may not match. * All users that exist in the database, regardless of the permissions granted to them, are represented by CUSTOM permissions.
DB Instance Details
You can select a DB instance to view the details.
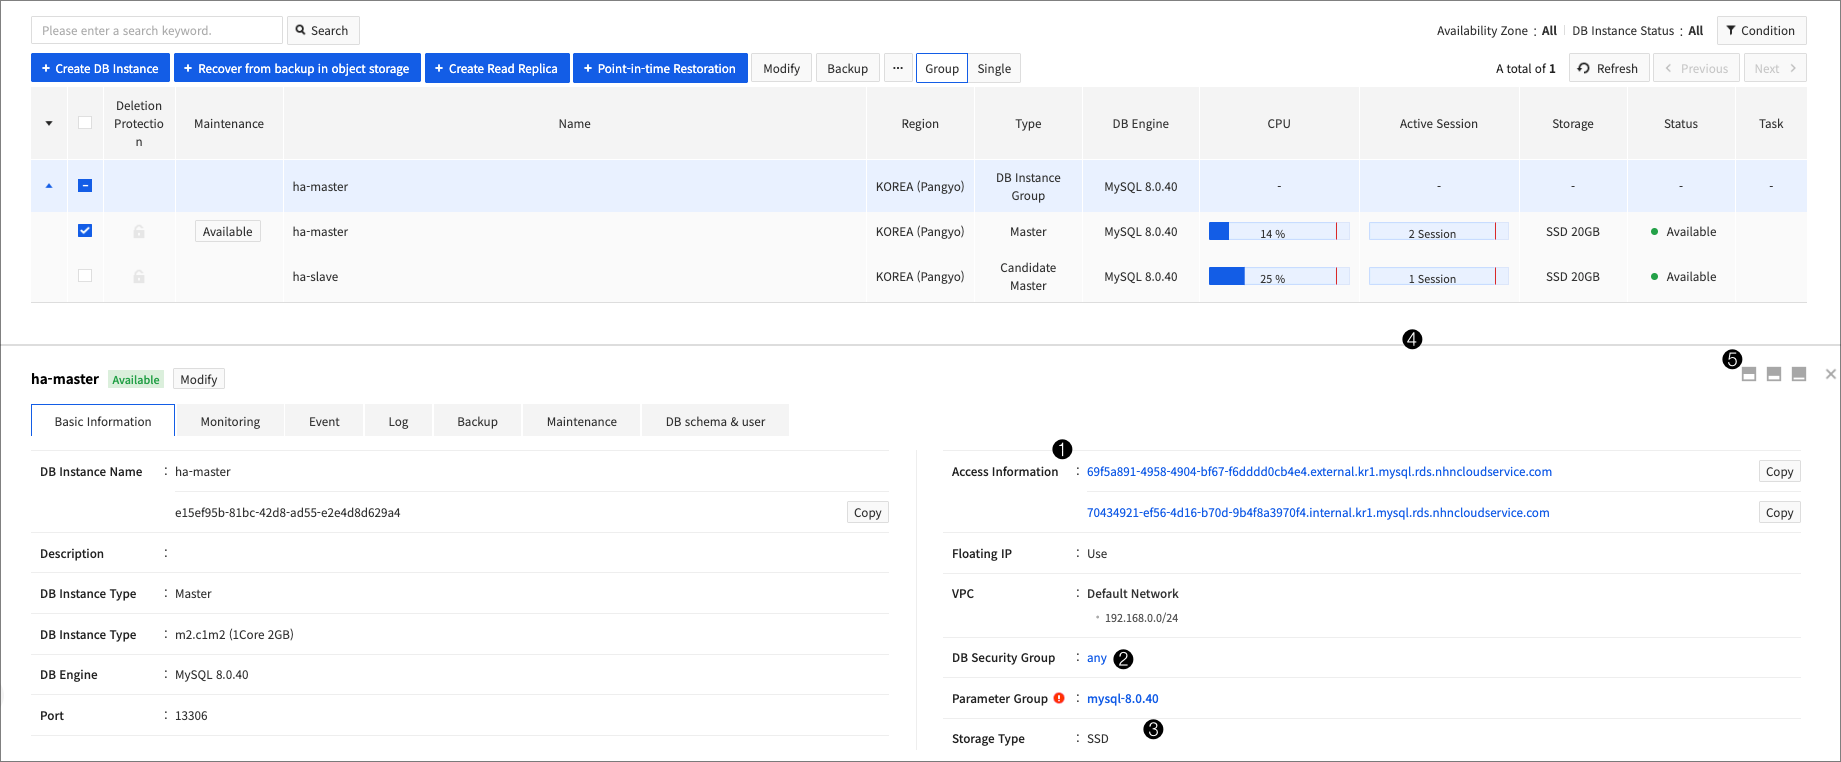
❶ When you click on the domain of the connection information, a pop-up window appears to confirm the IP address. ❷ When you click on DB Security Group, a pop-up window appears where you can check DB security rules. ❸ Click on a parameter group to go to a screen where you can see the parameters. ❹ Drag and drop the screen to adjust the height of the Details information panel. ❺ You can adjust the height of the Details information panel to a pre-determined height.
Access Information
When you create a DB instance, it issues an internal domain. The internal domain refers to the IP address that belongs to the user's VPC subnet. For high-availability DB instances, the internal domain does not change even if the Standby is changed to a new Primary due to failover. Therefore, unless there is a special reason, applications must use the internal domain for access information.
If you created a floating IP, issue additional external domains. The external domain points to the address of the floating IP. Because external domains or floating IPs are accessible from outside, you must protect the DB instance by setting the rules of DB security group appropriately.
Virtual IP
Starting with DB instances created after the May 2025 maintenance, VIP (Virtual IP) is supported. The VIP is an IP address within the user's VPC subnet. For high-availability DB instances, the VIP is always the current Primary. Application connection information must use either the VIP directly or the internal (VIP) domain.
For DB instances created before the May 2025 maintenance, you can add a VIP by selecting Add VIP in the NHN Cloud console. When a VIP is added, both the existing internal domain and the internal (VIP) domain are provided. However, if a failover occurs, the VIP is the Standby, while the internal domain may not be. Therefore, after adding a VIP, you must update the application's connection information to use either the VIP or the internal (VIP) domain.
Note
After the maintenance in September 2025, VIP will no longer be supported in the Japan (Tokyo) region and some public projects. (You cannot connect to a VIP from an instance or DB instance in a different subnet.) In environments that do not support VIPs, VIPs created after the May 2025 maintenance will not be deleted, but will no longer be visible in the console.
Log
You can view and download various log files from Log tab of DB instance. Log files are rotated to the settings set as below. Some log files can be enabled or disabled in the parameter group.
| Item | Rotate settings | Whether or not to change | Related parameter |
|---|---|---|---|
| error.log | 10 of 100MB | fixed | |
| slow_query.log | 40 of 100MB | fixed | slow_query_log |
| general_log.log | 40 of 100MB | fixed | general_log |
| server_audit.log | 30 of 20MB | Changeable | server_audit_loggingserver_audit_file_rotations |
| mysql-bin.xxxxxx | 5 days | Changeable | binlog_expire_logs_seconds |
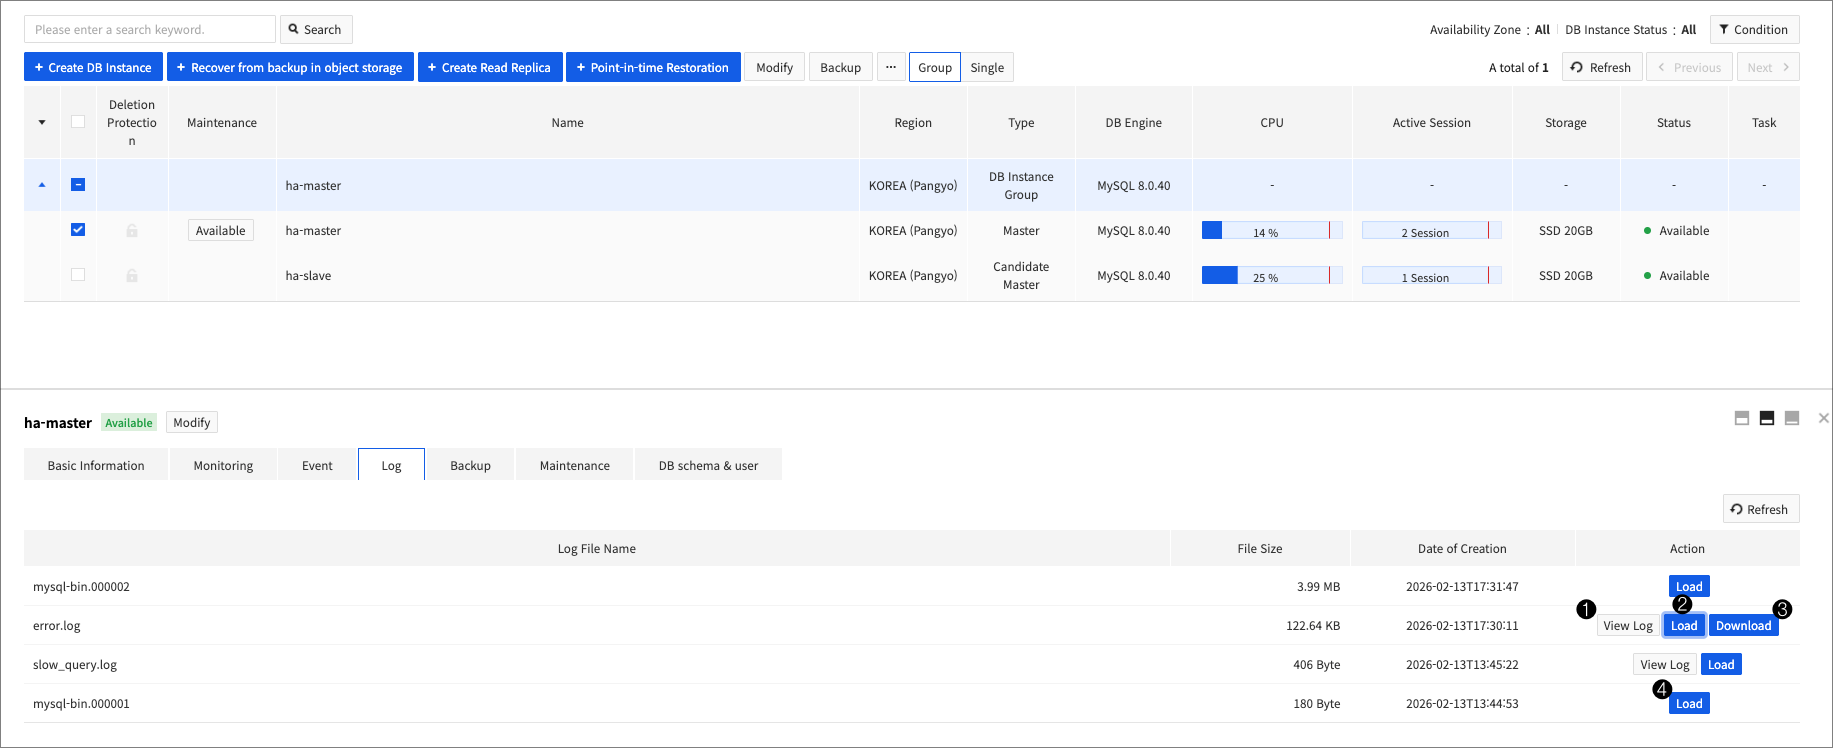
❶ Click on View Logs, and you will see a pop-up window where you can check the contents of the log file. You can check logs up to 65,535 Bytes. ❷ When Import is clicked, the request is made to download the log file for DB instance. ❸ When download is ready, Download button will be exposed. Click to download the log.
Caution
When Import is clicked, the log file is uploaded to backup storage for approximately 5 minutes and the backup storage capacity will be charged to the size of the log file. Click on Download to charge Internet traffic as the size of the log file.
❹ For binary logs, you can download them in two forms. Click on Import and you will see a pop-up window where you can select the type of binary log.

❺ Select to use the mysqlbinlog utility to convert the binary log into SQL file and then download it.
Maintenance
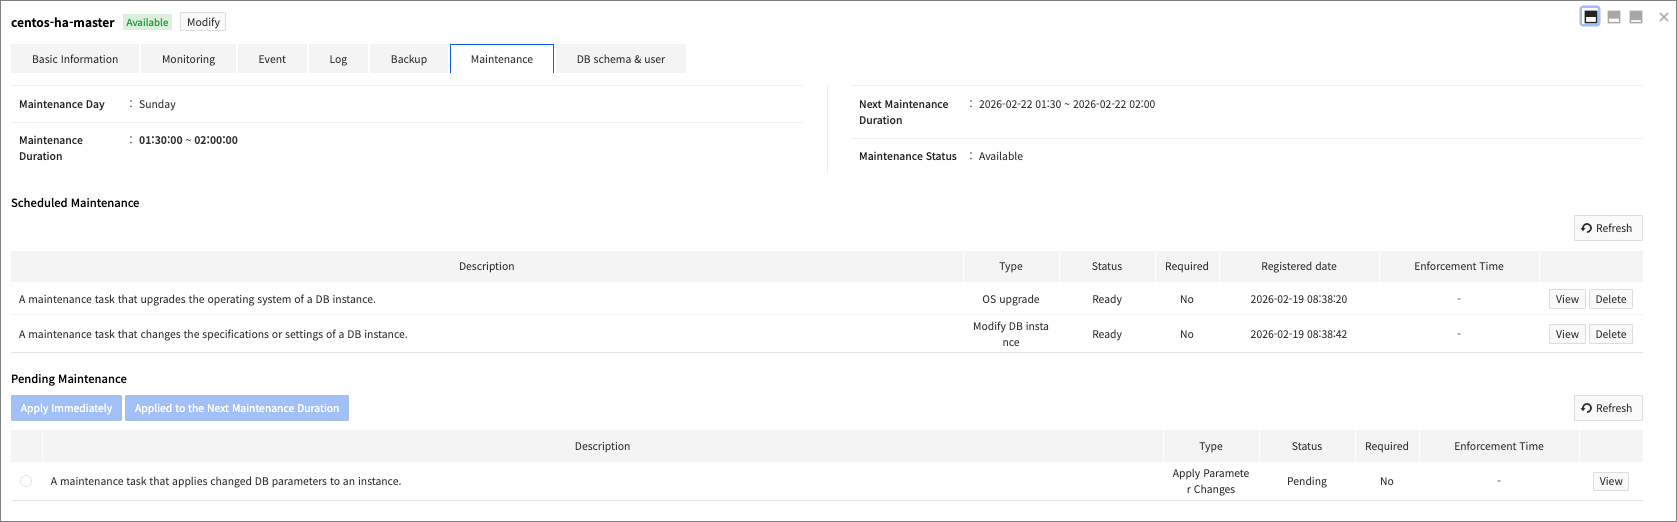
The Maintenance tab allows you to monitor settings and status, and manage maintenance operations for your DB instance.
Maintenance Information
At the top of the Maintenance tab, you can view the maintenance configuration details for the current DB instance.
| Item | Description |
|---|---|
| Maintenance Start Day | The maintenance start day set for the DB instance. |
| Maintenance Duration | The maintenance duration range set for the DB instance. |
| Next Maintenance Duration | The date and time when the maintenance task is next scheduled to run. |
| Maintenance Status | Indicates the current maintenance status. This can be one of None, Next Apply, Applying, Required, or Available. |
Note
Even if you haven't set a maintenance duration, you can view the randomly assigned duration here.
Upcoming Maintenance
Upcoming Maintenance is a list of tasks scheduled to be executed during the next maintenance duration. When you perform actions such as modifying a DB instance or upgrading the DB engine version and select Apply in the Next Maintenance Duration, the task is added to this list.
| Item | Description |
|---|---|
| Description | A description of the maintenance task. |
| Type | The type of maintenance task. |
| Status | The current status of the maintenance task. |
| Required | Indicates whether the maintenance task is required. |
| Registration Date | The date the maintenance task was registered. |
| Mandatory Date | If the task is required, it will be automatically applied after this date. |
Upcoming maintenance tasks can be excluded from the maintenance duration by selecting them and clicking Delete or Hold. If deleted, these tasks are canceled. To apply them again in a future duration, you must perform the original action once more. Provider maintenance tasks will be moved to the Pending Maintenance list. You can move them back to the Upcoming Maintenance list at any time from the Pending Maintenance list.
Pending Maintenance
Pending Maintenance is a list of Provider maintenance tasks provided by NHN Cloud. This includes operations such as applying parameter group changes and migrations for hypervisor maintenance.
| Item | Description |
|---|---|
| Description | A description of the maintenance task. |
| Type | The type of maintenance task. |
| Status | The current status of the maintenance task. |
| Mandatory | Indicates whether the maintenance task is mandatory. |
| Forced Date | If the task is mandatory, it will be applied automatically after this date. |
You can select a pending maintenance task and then click Next to select the execution time.
Apply Immediately: apply immediately upon request. Click Confirm to execute immediately.
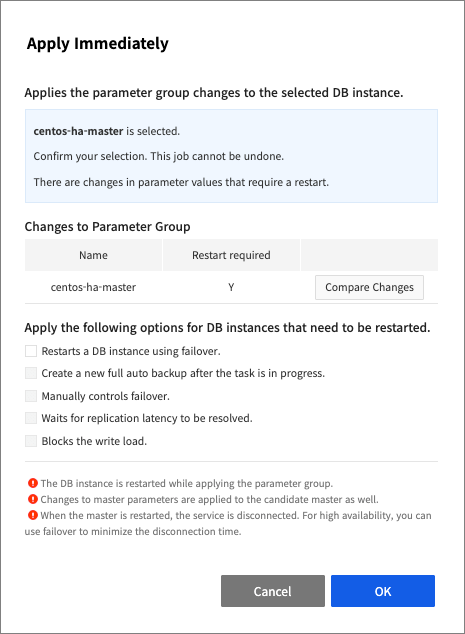
Apply in the Next Maintenance Duration: apply during the next maintenance duration. Click Confirm to move this task to the Upcoming Maintenance list.
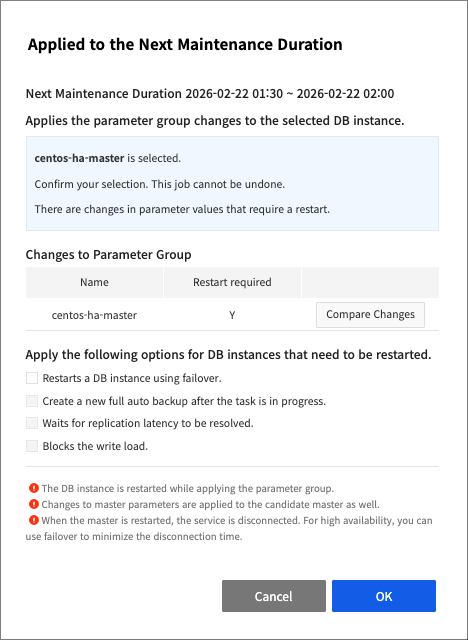
Caution
Required maintenance tasks can be applied at any time up to the mandatory application date. However, after the mandatory application date, they will automatically be performed during the next maintenance period.
Note
If a maintenance task requires a restart, a pop-up screen will appear, allowing you to select additional options, such as failover or backup. For high-availability DB instances, you can minimize service downtime by using a restart with failover.
Modify DB instance
You can easily change various items in DB instances created through console. Changes requested are applied to DB instances sequentially. If restarting is required during the application process, apply all changes and restart DB instance. The following are the items that cannot be changed and require restarting.
| Item | Whether or not you can change | Whether or not you need to restart |
|---|---|---|
| Availability Zone | No | |
| DB Engine | Yes | Yes |
| DB Instance Type | Yes | Yes |
| Data Storage Type | No | |
| Name | Yes | No |
| Description | Yes | No |
| DB port | Yes | Yes |
| VPC Subnet | No | |
| Floating IP | Yes | No |
| Parameter group | Yes | Determined by whether or not to restart changed parameters |
| DB Security Group | Yes | No |
| Backup Settings | Yes | No |
| Storage Auto Scale | Yes | No |
For high-availability DB instances, if there are any changes to items that need to be restarted, it provides a restart capability using failover to increase stability and reduce disconnected time.
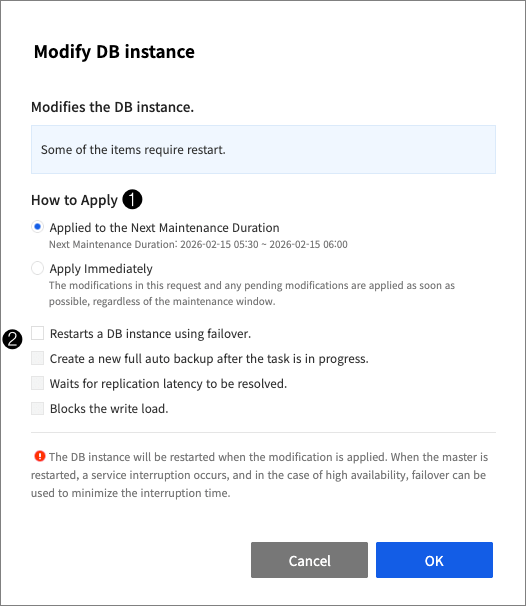
❶ Modify your DB instance and schedule the update by selecting either Apply in the Next Maintenance Duration or Apply Immediately. ❷ If you do not use 'Reboot with Failover', changes will be applied sequentially to the Primary and Standby, followed by a restart of the DB instance. For more details, please refer to the Manual Failover section for High Availability DB instances.
Upgrade DB instance operating system
Supports DB instance operating system upgrades. By upgrading the operating system, you can resolve security vulnerabilities or respond to the end of life (EOL) of the operating system. Caution is required when upgrading the operating system because it may result in service disruption. Highly available DB instances can minimize service disruption through failover.
You can check the operating system information of the current DB instance on the DB instance details screen.
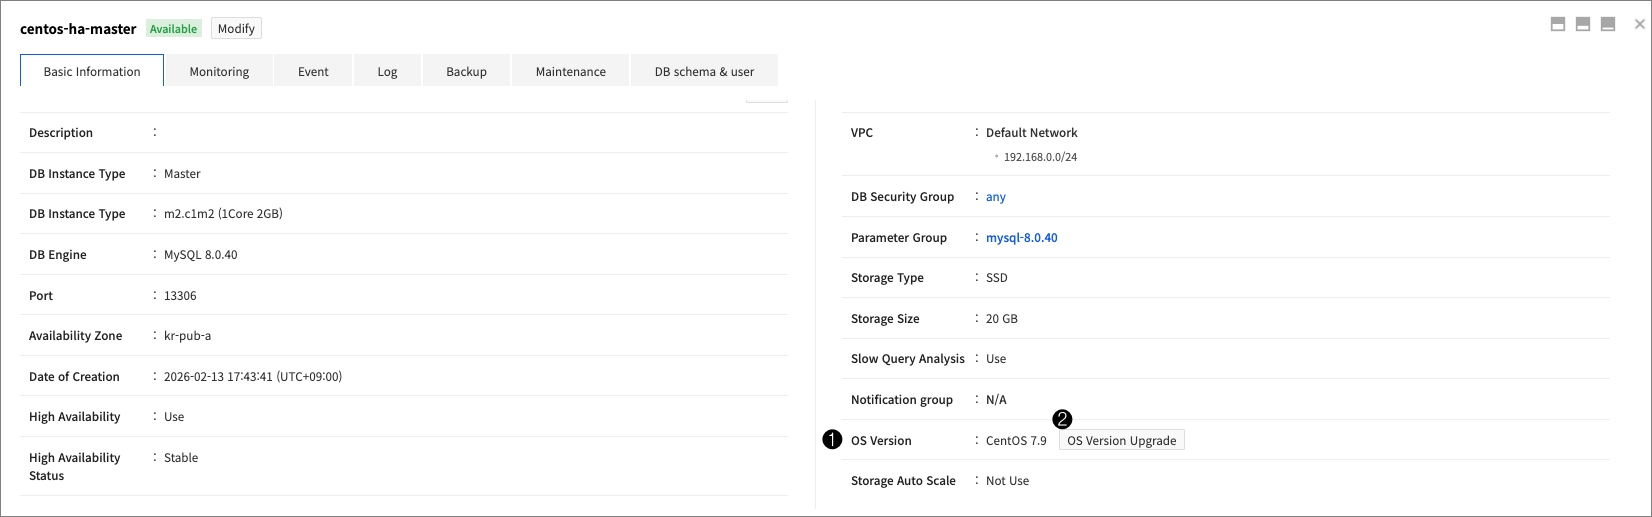
❶ You can check the operating system information of the DB instance. ❷ If the operating system is eligible for a version upgrade, the OS Version Upgrade button appears.
Operating system version upgrades behave differently depending on whether you are in a highly available configuration. For high availability instance, the operating system version upgrade is performed using failover. For non-high availability, the operating system version upgrade is performed by restarting the DB instance.
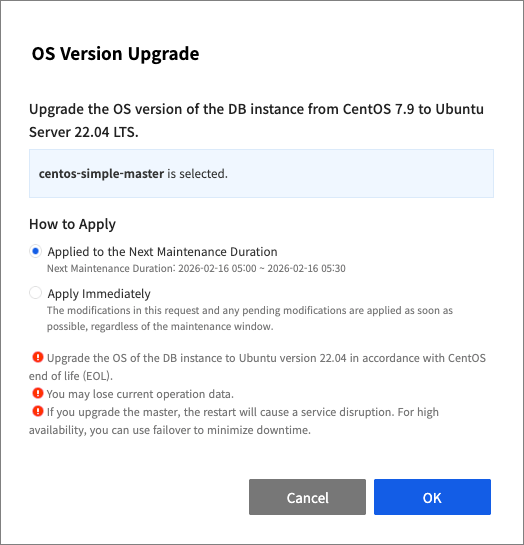
When you click the OS Version Upgrade button for a single DB instance, the following pop-up screen appears.
The maintenance feature is also available when upgrading the operating system version of a single DB instance.
When you click the Upgrade Operating System Version for High Availability DB Instance button, the pop-up screen shown below appears. For more information, see Manual failover item of High Availability DB Instances.
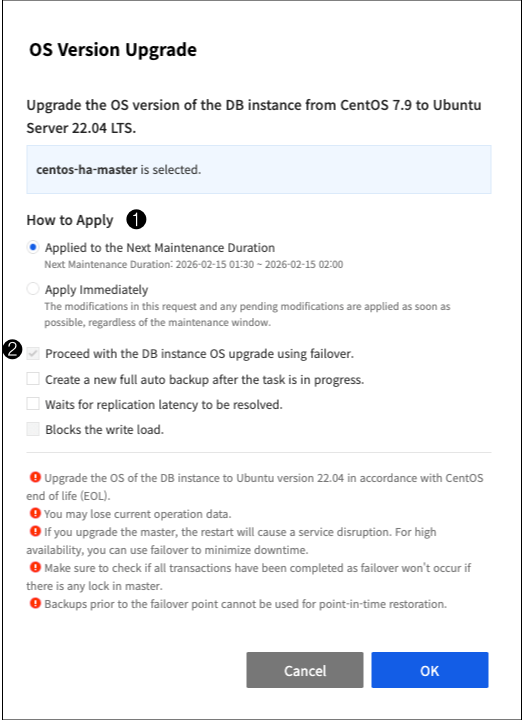
❶ You can use the maintenance feature through the Maintenance Application Method settings. ❷ Only the With Failover method is provided.
Delete DB Instance
You can delete DB instances that are no longer in use. If you delete a Primary, you will also delete both the Standby and Read Replicas that belong to that replication group. Because deleted DB instances cannot be recovered, we recommend that you enable the Delete Protection settings for important DB instances.
Backup
You can prepare in advance to recover the database of your DB instance in case of failure. You can perform backups from the console whenever necessary or you can set up periodic backups. Refer to Backup for more information.
Restoration
You can use backups to restore data to any point in time. Restore always creates a new DB instance and cannot be restored to an existing DB instance. Refer to Restore for more information.
Secure Capacity
If the capacity of the data storage is insufficient due to the excessive generation of binary logs from rapid load, you can delete the binary logs using Secure Capacity feature in console. When you select Secure Capacity in console, you will see a pop-up window where you can select the binary logs for DB instance. Select the binary log and press Confirm to delete all binary logs created prior to the selected item. The Secure Capacity is a feature that temporarily secures capacity. If you keep running out of capacity, you must set the storage period for the binary log or expand the size of the data storage to match your service load.
Note
You can set the storage period for binary logs with the binlog_expire_logs_seconds parameter.
Caution
Depending on the deleted binary logs, point-in-time restoration may not be possible.
Expand Storage Size
You can scale up the data storage size of a DB instance. The expansion takes effect immediately without restarting the DB instance.
Auto Scale Storage
You can automatically scale the data storage size of a DB instance. With auto storage expansion, you can maintain the availability of your database by automatically scaling up when data storage runs out of capacity.
To use auto storage scaling, you must enable ** Auto Scale Storage** when creating and modifying DB instances.
When you enable auto scale storage, you can set three options * Storage Auto Scale Conditions: Automatically expand storage when storage utilization is above a set value for more than 5 minutes. * Storage Auto Scale Max: The maximum size that storage auto-scale can grow to. * Storage Auto Scale Cooldown: Set the amount of time after storage auto scale cooldown runs once before the feature is enabled again.
The amount of increase when the auto scale storage feature runs is set to the largest of the following values * 10 GB * 10% of storage size * Data storage usage growth in the last hour * cooldown (in hours)
Apply parameter group changes
Changes made to a parameter group linked to a DB instance are not automatically applied to that instance. If the parameters currently applied to the DB instance differ from the settings in the linked parameter group, an Apply Parameter Changes maintenance task is created, and the maintenance status is updated.
You can apply parameter group changes to a single DB instance or multiple DB instances using the following methods:
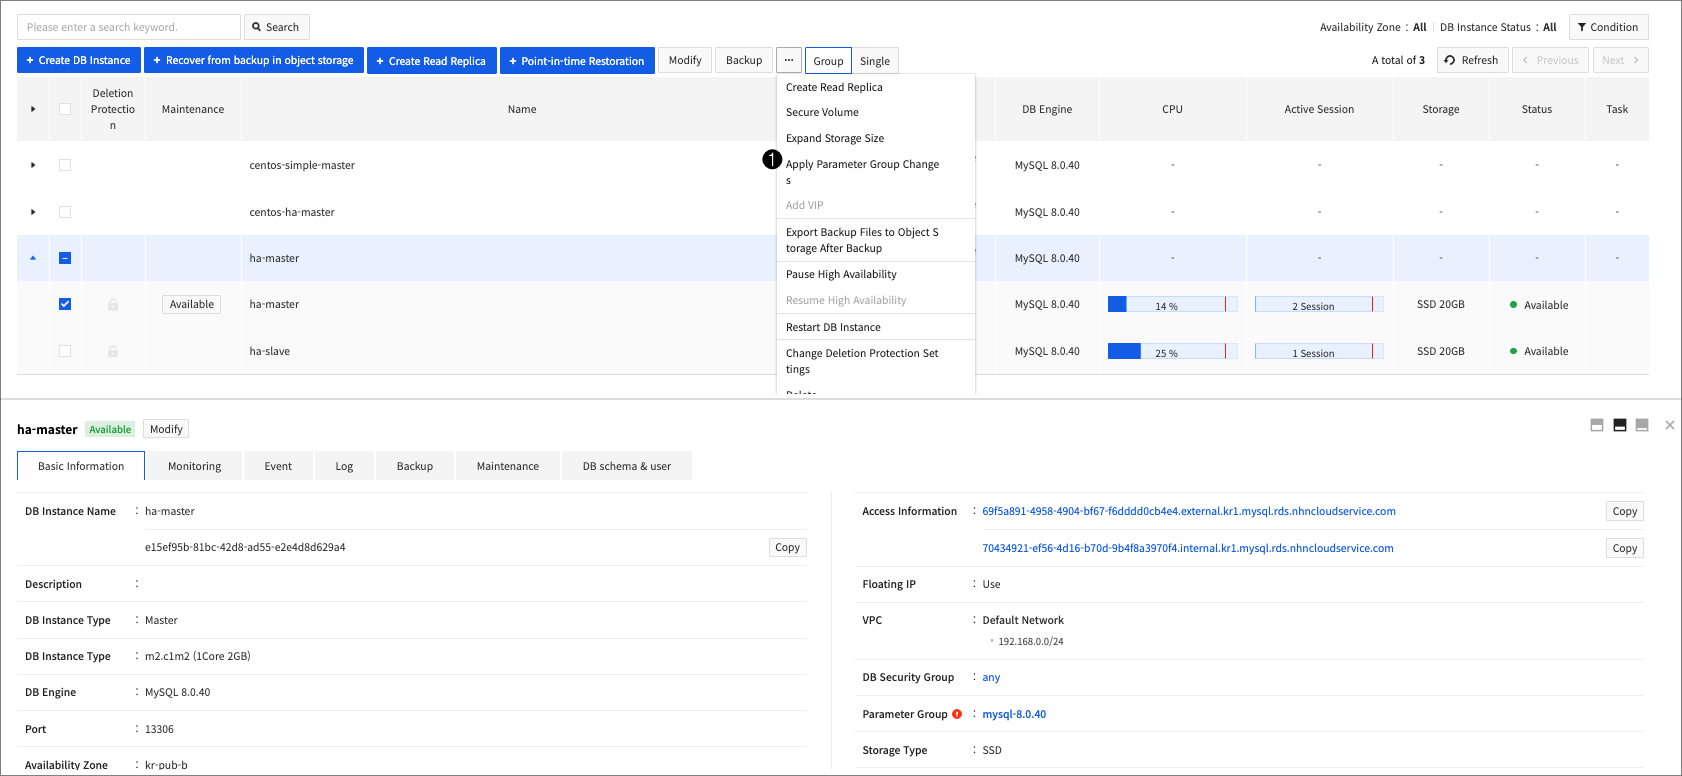
❶ Select the target DB instance, then click Apply Parameter Group Changes from the dropdown menu.
You can apply parameter group changes by choosing either Apply in the Next Maintenance Duration or Apply Immediately through the maintenance feature.
If the parameters in the parameter group that require a restart are changed, the DB instance is restarted during the process of applying the changes.
High-availability DB instances provide a restart feature using failover to increase stability and reduce disconnected time.
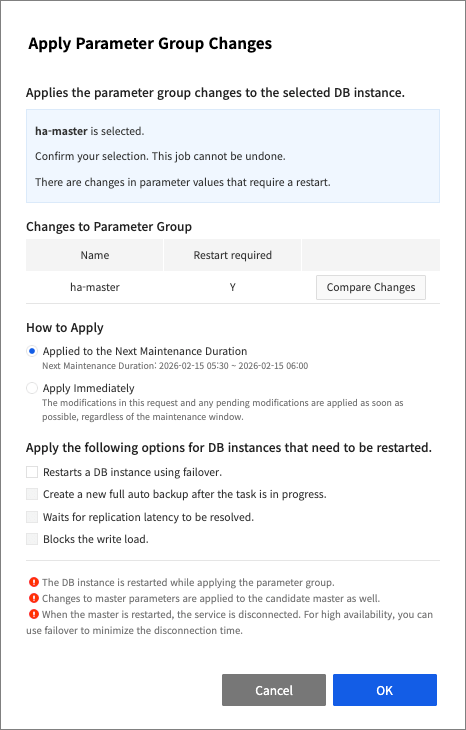
If restart with failover is not enabled, the DB instance is restarted after the changes are sequentially applied to the Primary and Standby. For more information, refer to Manual failover item in a high availability DB instance.
Recover from backup in Object Storage
You can upload an external MariaDB backup file to NHN Cloud Object Storage to restore it to DB instance in RDS for MariaDB. For more information, refer to Restore with External MariaDB Backup.
Export backup files to Object Storage after backup
After backup, you can export backup files to Object Storage. Refer to Export Backup for more information.
Read Replica
To improve read performance, you can create Read Replicas that can be used for read-only. You can create up to 5 Read Replicas per Primary. You cannot create Read Replicas of Read Replicas.
Create Read Replica
To create Read Replicas, you need backup files and binary logs created with the Enable table lock option among DB instances in the replication group. If you do not have a backup file, use the following steps to select DB instance for which you want to back up.
❶ Read Replica with auto backup enabled ❷ Standby with auto backup enabled ❸ Primary with auto backup enabled
If there is no DB instance that meets the criteria, the request to create a Read Replica will fail.
Caution
The Read Replica creation time may increase in proportion to the database size of the Primary. For DB instances that are backed up, there may be a drop in storage I/O performance during the Read Replica creation process.
Note
Backup storage charges can be as much as the size of a binary log required for the Read Replica creation process.
To create a Read Replica from the console,
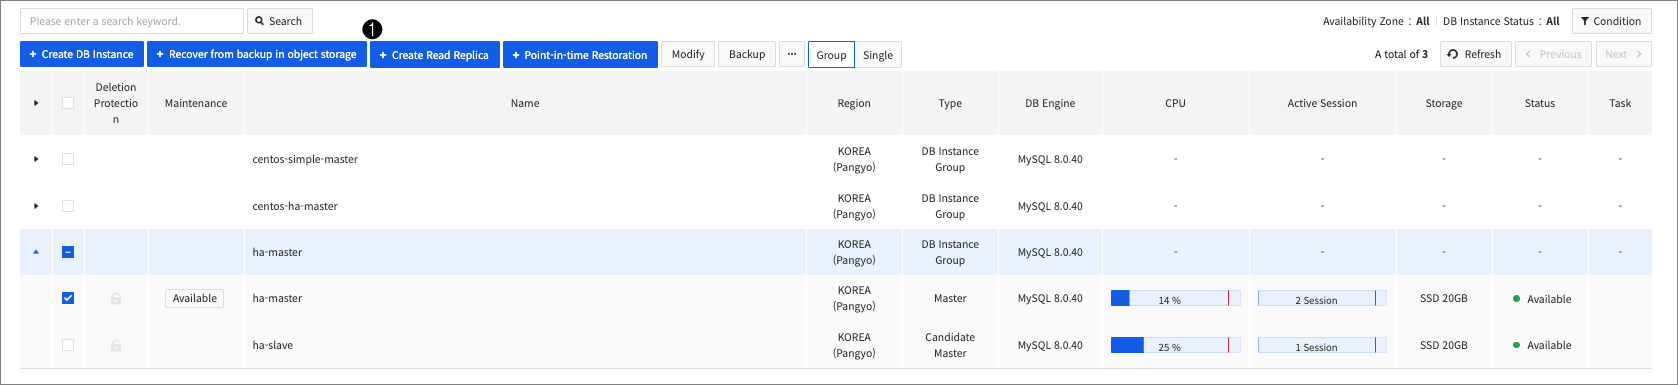
❶ Select the source DB instance and click on Create Read Replica
You can create a Read Replica using the settings below.
Non-Editable Items
When you create a Read Replica, you cannot change the items listed below because they follow the settings of source DB instance.
- DB Engine
- Data Storage Type
- User VPC Sub-nets
Availability Zone
Select the availability zone for Read Replica. Refer to Availability Zone for a detailed description.
DB Instance Type
It is recommended that Read Replicas be created to the same specification or higher than the Primary; creating them to a lower specification can cause replication delays.
Data Storage Size
It is recommended to make it the same size as the source DB instance. If you set a smaller size, the replication process may be interrupted due to insufficient data storage capacity.
Floating IP
Select whether or not to use floating IP for Read Replicas. Refer to Floating IP for a detailed description.
Parameter group
If you do not need to change replication-related settings when selecting a parameter group for a Read Replica, we recommend that you select the same parameter group as the original DB instance. Refer to Parameter Group for a detailed description of the parameter groups.
DB Security Group
Select the DB security group that you want to apply to Read Replicas. Because the rules required for replication are applied automatically, you do not need to add replication-related rules to DB security group separately. Refer to DB security group for a detailed description of the DB security group.
Backup
Select backup settings for the Read Replica. Refer to Backup and Restore for a detailed description of backup.
Default notification
Select whether or not to enable default notifications, refer to default notifications for a detailed description.
Deletion Protection
Select whether or not to enable deletion protection. Refer to Deletion Protection for a detailed description.
Promote Read Replica
The process of breaking the replication relationship with the Primary and converting a Read Replica to an independent Primary is called promotion. The promoted Primary will act as an independent DB instance. If there is a replication delay between the Read Replica and the Primary that you want to promote, the promotion will not take place until the delay is resolved. Once promoted, a DB instance cannot be reverted to the previous replication relationship.
Caution
If the Primary DB instance is in an abnormal state, you cannot proceed with the promotion operations.
Note
You can perform promotion operations from the same region's console as the region where the Read Replica is located.
Force Promotion of Read Replicas
Force promotion is processed based on current point-in-time data of the Read Replica, regardless of the state of the Primary or original region. Reproduction delays can result in data loss. Therefore, we do not recommend using this feature unless you are in a situation where you urgently need to put the Read Replica into service.
Stop Replication of Read Replicas
Read Replicas can be stopped for several reasons. If the status of the Read Replica is Replication stopped, you must quickly determine the cause and perform normalization. If the Replication stopped status persists for a long time, the replication delay will increase. If you do not have the binary log required for normalization, you must rebuild the Read Replica. The reason for replication stop can be determined by the SHOW SLAVE STATUS command in the Read Replica. If the value
of Last_Errno is 1062, you can call the Procedure below until the error disappears.
mariadb> CALL mysql.tcrds_repl_skip_repl_error();Rebuild Read Replica
If you can't resolve the replication issue of Read Replica, you can restore it to its normal state by rebuilding. This process deletes all databases in the Read Replica and rebuilds it anew based on the Primary database. During rebuilding, Read Replicas are unavailable to use. Rebuilding Read Replicas requires backup files and binary logs created with the Enable Table Lock option among DB instances in the replication group. If you don't have a backup file, refer to Create Read Replica for actions and precautions.
Note
Connection information (domain, IP) does not change after rebuilding.
Restart DB instance
You can restart a DB instance when you restart MariaDB or want to manually do failover a high availability DB instance. We recommend that you perform it during low service load times to minimize restart times. For high availability DB instances, if restarting with failover is not enabled, restart the Standby first, then restart the Primary. For restarting with failover feature, refer to Manual Failover item.
To restart a DB instance from the console
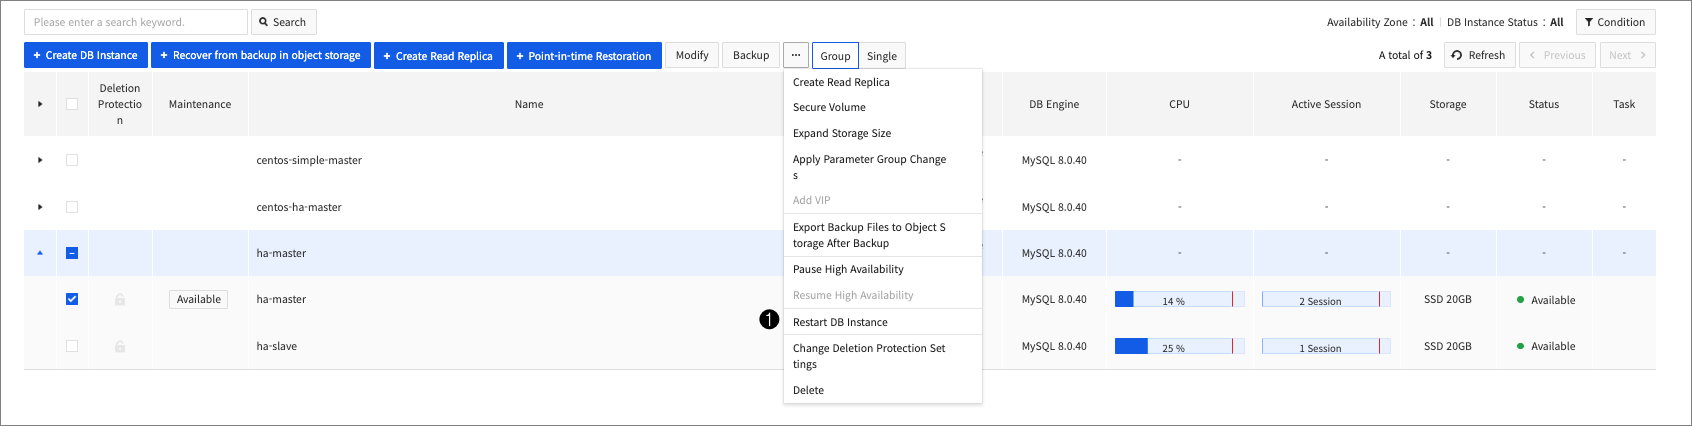
❶ Select the DB instance you want to restart and click on Restart DB instance menu from the drop-down menu.
DB instance force restart
If MariaDB in the DB instance is not working properly, you can force a restart. For forced restart, issue a SIGTERM command in MariaDB and wait 10 minutes for it to shut down normally. If MariaDB shuts down normally within 10 minutes, reboot the virtual machine afterward. If it does not shut down normally within 10 minutes, force a reboot of the virtual machine. If the virtual machine is forced to reboot, some of the transactions you are working on might be lost and the data volume might be corrupted, making recovery impossible. After a forced restart, the state of the DB instance might not return to the available state. Contact Customer Support if this situation occurs.
Caution
Because there is a possibility of data loss or data volume corruption, this feature should not be used except in urgent and unavoidable circumstances.
Note
For high availability DB instances, you cannot force restart.
To force restart a DB instance, from the console
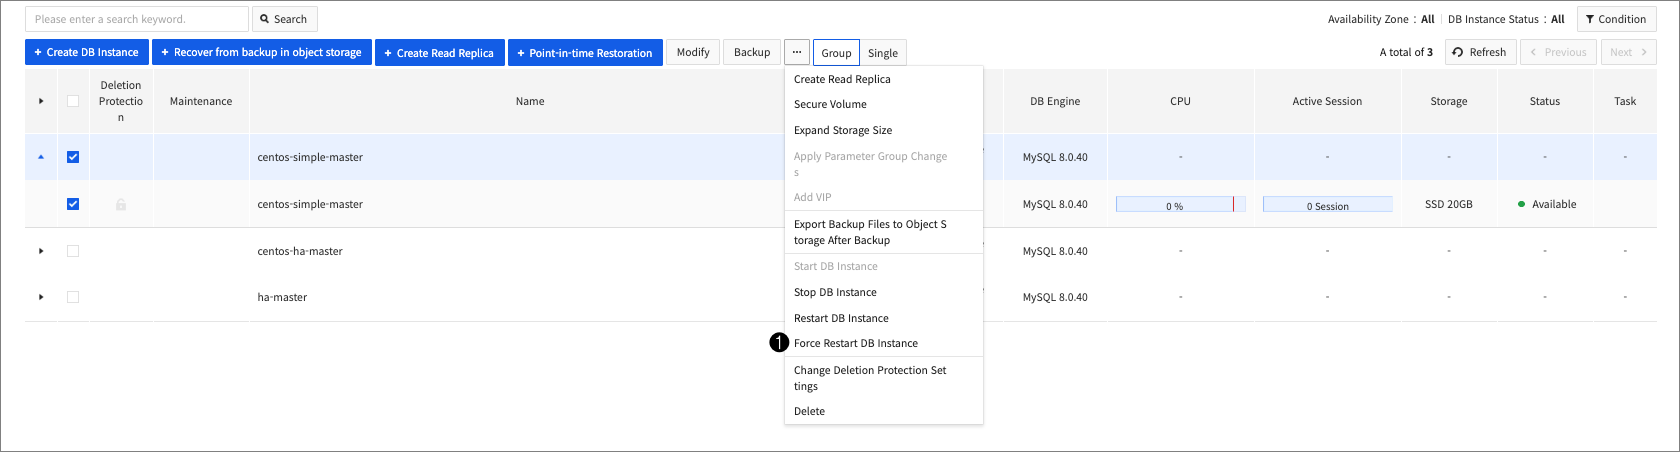
❶ Select the DB instance for which you want a forced restart and from the drop-down menu, click on Force Restart DB instance menu.
Change Deletion Protection Settings
Enabling Delete Protection protects DB instances from being accidentally deleted. You cannot delete DB instances until Delete Protection is disabled. To change Delete Protection settings
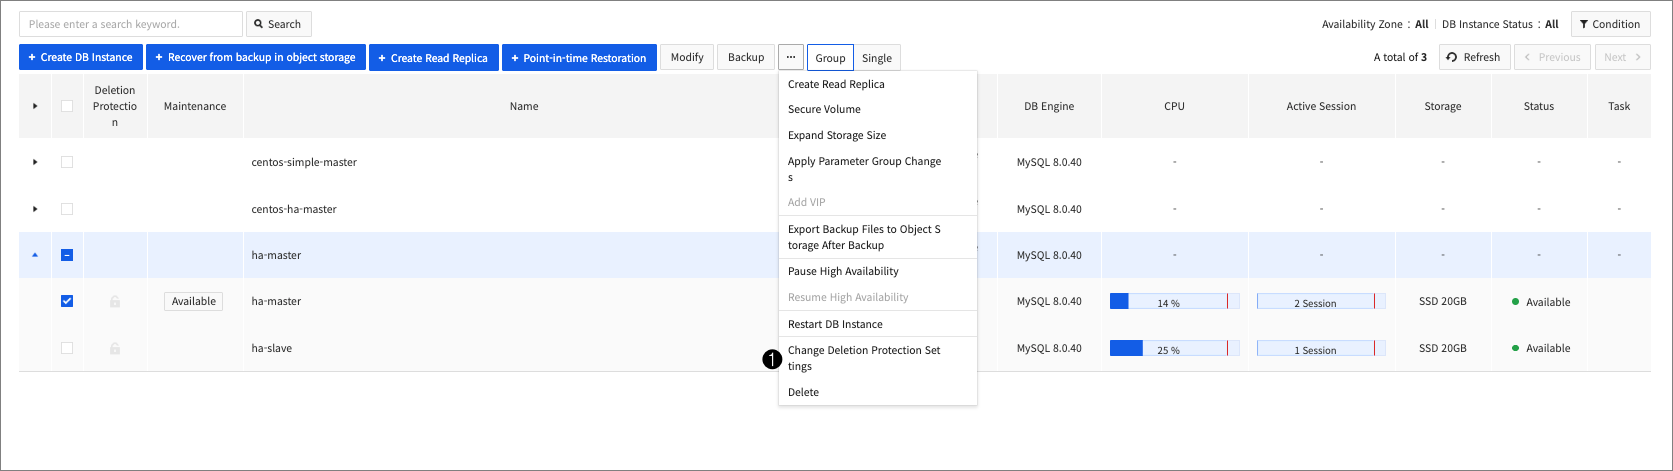
❶ If you select the DB instance for which you want to change the Deletion Protection settings and click on Change Deletion Protection Settings menu from the drop-down menu, a pop-up window will appear.

❷ Change the Delete Protection settings and click on Confirm.
High Availability DB Instances
High availability DB instances increase availability, data durability, and provide fault tolerant databases. High availability DB instances consist of Primary and Standby and are created in different availability zones. Standby is a DB instance for failover and is not normally available. For high availability DB instances, backups are performed on the Standby.
Note
For high availability DB instances, if you set to use MariaDB query statement to force replication from another DB instance or from a master in external MariaDB, high availability and some features do not work properly.
Failure Detection
Standby has a process for detecting failures, which periodically detects the state of the Primary. This detection period is called ping interval and takes failover if four consecutive health checks fail. The shorter the ping interval, the more sensitive to the fault respond is, and the longer the ping interval, the less insensitive the fault respond is. It is important to set the appropriate ping interval for the service load accordingly.
Note
When the Primary's storage usage is full, the high availability monitoring process detects it as a failure and takes action, which you should be taken note of.
Automatic Failover
When the Standby fails the Primary's health check four times in a row, it determines that the Primary is unable to provide service and automatically performs a failover. In order to prevent split brains, disconnect all user security groups assigned to the failed Primary to block external connections, and the Standby will take over the role of the Primary. A record in the internal domain for access are changed from the failed Primary to the Standby, so no changes to the application are required. When failover is completed, the type of the failed Primary changes to Failed Over Primary and the type of Standby changes to the Primary. No failover is performed until the Failed Over Primary is recovered or rebuilt. The new Primary takes over all automatic backups of the Failed Over Primary. Point-in-time restoration using existing backups is not supported because the Primary changes during failover and all binary logs are deleted. You can restore point-in-time from the time the new backup was performed on the new Primary.
Note
As the high availability feature is based on a domain, if a client trying to connect is in a network environment where the DNS server cannot be reached, the DB instance cannot be accessed through the domain, and normal connection is not possible in the event of failover. It takes approximately 3 seconds for the changes to A record in the internal domain to take effect, but may vary depending on the DNS Cache policy in the client environment where attempting to connect.
Caution
If the position number value of the binary log between Primary and Standby differs by more than 100,000,000, there is no failover.
If replicate-ignore-db or replicate-ignore-table is applied, changes to that DB or table will not be replicated and failover may fail.
Failed Over Primary
A Primary that fails and conducts failover is called Failed Over Primary. Backups of Failed Over Primary are not automatically performed, and all other features other than Failed Over Primary recovery, rebuild, separate, and delete are not performed.
Recover Failed Over Primary
If the data is not consistent during failover and the binary log is not lost from the point of failure to the point of attempting recovery, the Failed Over Primary and the new Primary can be recovered back to the high availability configuration. Because it re-configure replication relationships with the new Primary in the database of the Failed Over Primary, recovery fails once the data became inconsistent or once the binary log required for recovery was lost.
If the Failed Over Primary fails to recover, you can re-enable the high availability feature by rebuilding.
Note
Recovery is not supported for DB instances where failover occurred before April 11, 2023.
To recover a Failed Over Primary, from the console
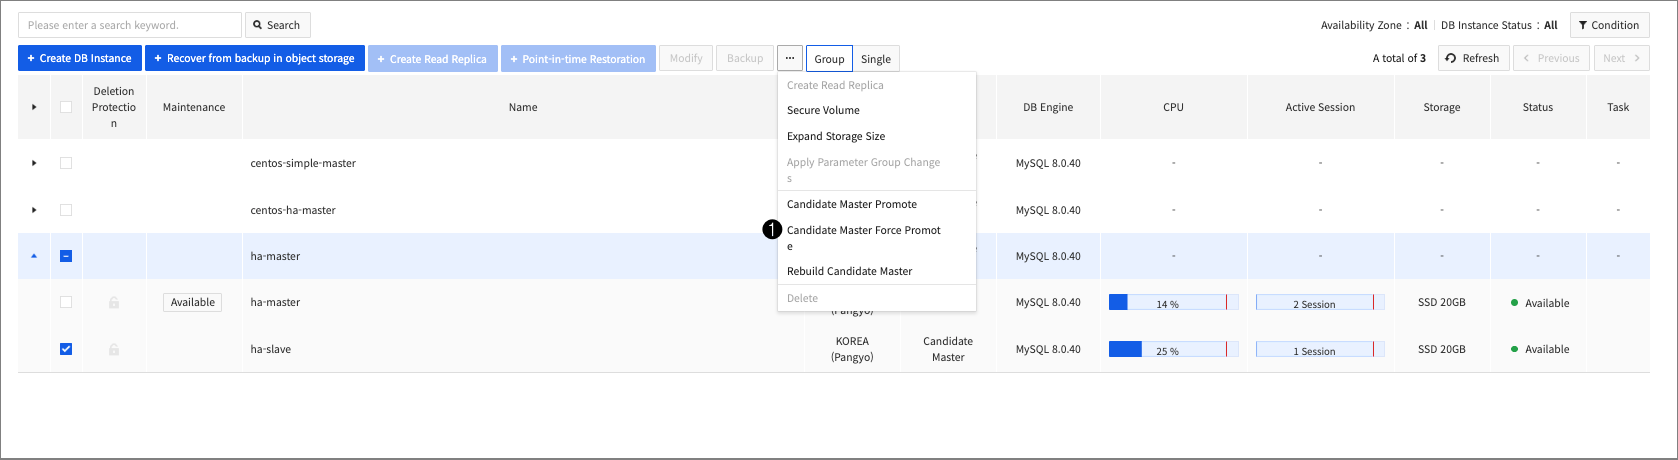
❶ Select the Failed Over Primary you want to recover from and click on Recover
Failed Over Primary menu from the drop-down menu.
Rebuild Failed Over Primary
If the Failed Over Primary fails to recover, you can re-enable the high availability feature by rebuilding. Unlike recovery, rebuild removes all databases from the Failed Over Primary and rebuilds them based on the new Primary's database. Rebuilding a Failed Over Primary requires backup files and binary logs created with the Enable Table Lock option among DB instances in the replication group. If you do not have a backup file, use the following order to select the DB instance to perform backup.
❶ Read Replica with auto backup enabled ❷ Primary with auto backup enabled
If there is no DB instance that meets the condition, the Failed Over Primary rebuild request fails.
Caution
In proportion to the size of the Primary's database, the time to rebuild the Failed Over Primary can be increased. For DB instances where backups are performed, storage I/O performance may be degraded during the Failed Over Primary rebuilding.
Note
Backup storage charges can be as much as the size of the binary log required for the Failed Over Primary rebuild process.
To rebuild a Failed Over Primary, from the console
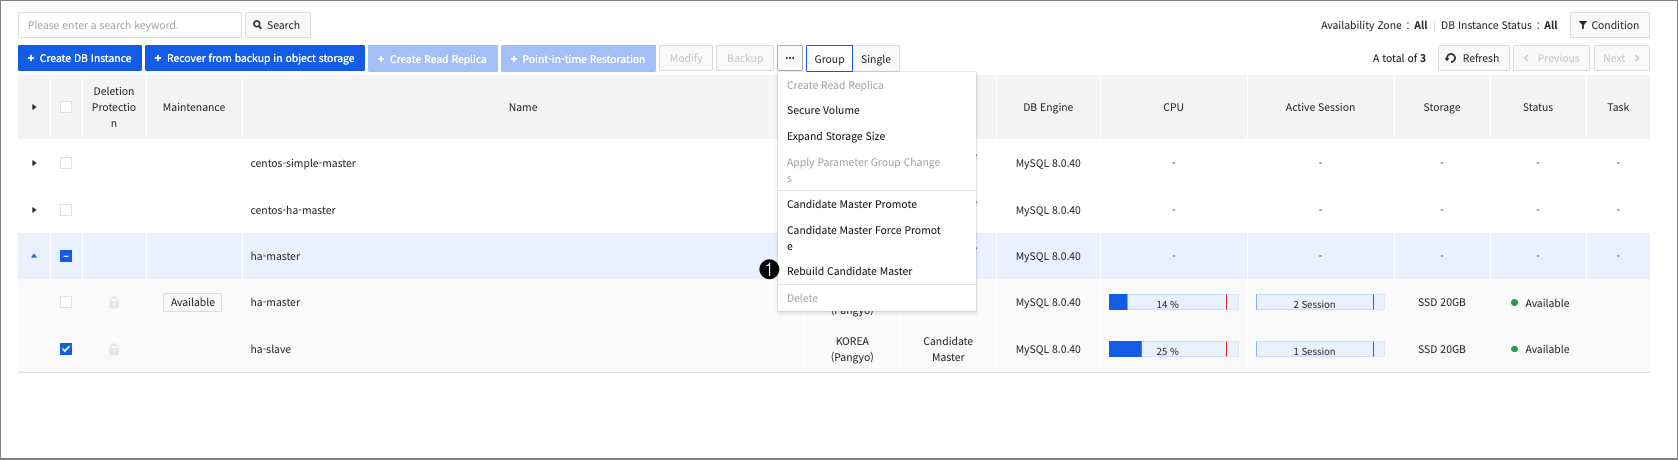
❶ Select the Failed Over Primary you want to rebuild and click on Rebuild Failed Over Primary menu from the drop-down menu.
Separate Failed Over Primary
If recovery of a Failed Over Primary fails and data correction is required, you can disable the high availability feature by separating that Failed Over Primary. The replication relationship between the separated Primary and the new Primary is broken, and each behaves as a normal DB instance. After separation, you cannot recover to the existing configuration.
To separate Failed Over Primary, from the console
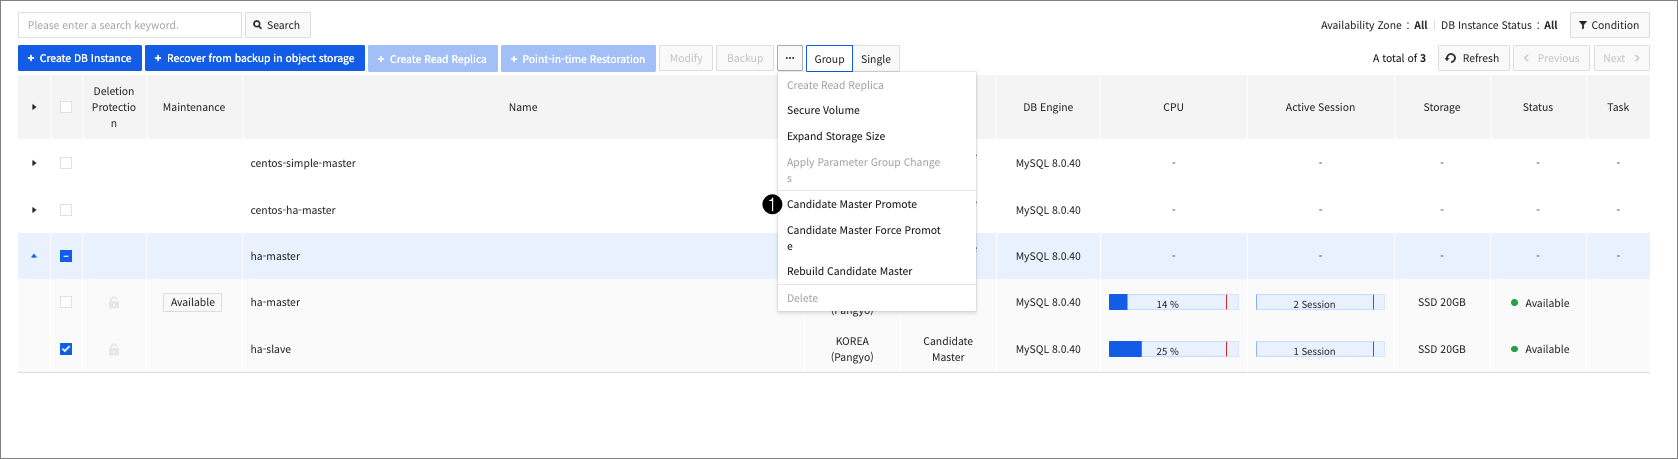
❶ Select the Failed Over Primary you want to isolate and click on Separate Failed Over Primary menu from the drop-down menu.
Manual Failover
For a high availability DB instance, you can select whether or not to restart with a failover when you perform an operation that accompanies a restart, which is as follows.
- Restart DB instance
- Changes items that need to be restarted
- Apply changes to parameters that require restart
- DB Instances migration for Hypervisor Check
After a restart using failover, the Standby will be restarted first. After that, the Standby becomes the Primary through failover, and the existing Primary will act as the Standby. At this point, the A record in the internal domain for the connection will be changed from Primary to Standby, so no application changes are required. The new Primary succeeds to all automatic backups of the old Primary. Point-in-time restoration with existing backups is not supported because the Primary changes during the failover and all binary logs are deleted. You can restore points-in-time from the time when the new backup is performed on the new Primary.
Note
Because the high availability feature is domain-based, if the client attempting to connect is in a network environment where the DNS server cannot be accessed, the DB instance cannot be accessed through the domain, and successful connection is not possible in the event of a failover. It takes approximately 3 seconds to reflect changes in the A record in the internal domain. The time required may vary depending on the DNS Cache policy of the client environment attempting to connect.
Caution
If the Seconds_Behind_Master value of the Read Replica included in the replication group with the Standby is greater than or equal to 1, replication delay is considered to have occurred and a manual failover will fail. It is recommended that you perform manual failover during off-peak hours. Restart failures due to replication delays can be verified through the Events screen.
When restarting with a failover, you can select the following additional items to increase stability.
Progress current point-in-time backup
Because all binary logs are deleted during the failover process, you can proceed with manual backups immediately after the failover is complete.
Manual Control of Failover
You can apply changes to the Standby first and then observe the trend, or you can control when you want to perform a failover at the exact time from the console. When you select Failover Manual Control, the ❶ console displays the Failover button after the Standby restarts. Click on this button to activate the failover, which can wait up to 5 days for the failover to occur. If the failover is not enabled within five days, the task will be automatically cancelled.
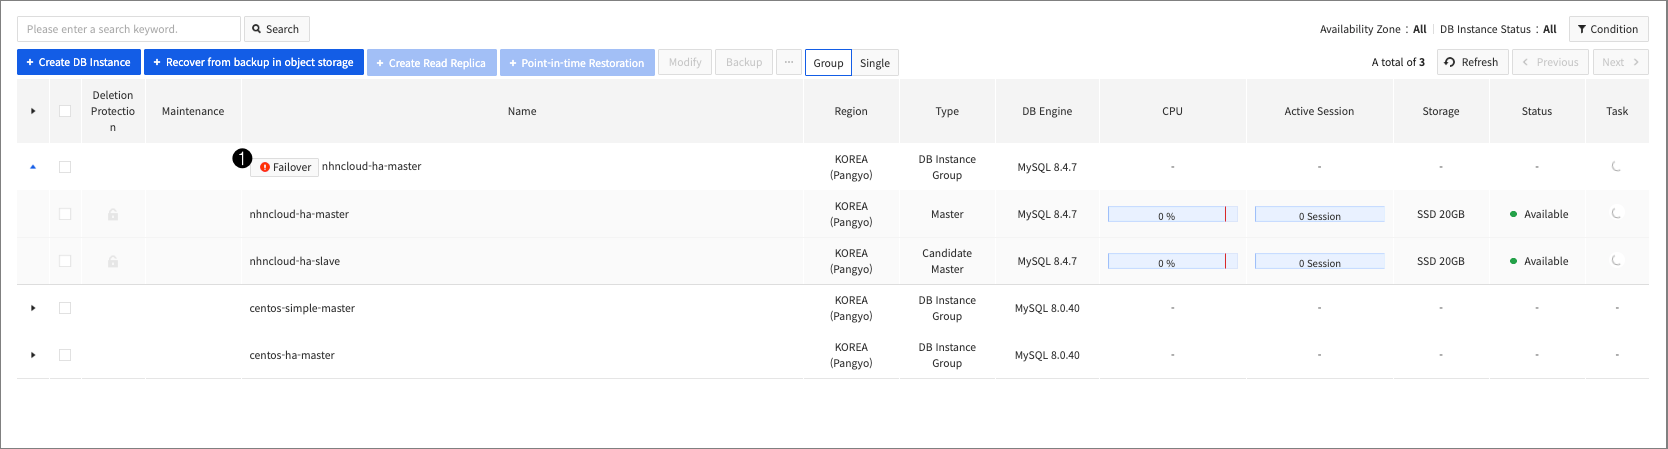
Caution
While waiting for a failover, no automatic failover occurs.
Waiting for Resolve Replication Delay
When you enable Resolve Replication Delays option, you can wait for replication delays for the Standby and Read Replicas in the Replication group to disappear.
Block write load
You can select to further block the write load while resolving replication delays. Blocking the write load puts the Primary in read-only mode and sets all change queries to fail immediately before performing the failover.
High availability suspended
High availability features can be temporarily stopped in situations where a temporary operation can cause a connection outage or heavy load. When a high availability feature is suspended, it does not detect a failure and does not perform a failover action. When a high availability feature is suspended, performing an operation that requires a restart does not restart the suspended high availability feature. It is not recommended to leave data replication in a pause state for an extended period of time because high availability feature is paused and data replication is successful or failure is not detected.
Rebuild Standby
Standby replication can be disrupted due to a variety of reasons, such as network disconnection, incorrect FEDERATED engine use, and replication settings from other Primaries. Standbys in a Stopped Replication state do not perform automatic failover. To resolve a Standby's Stopped Replication, the Standby needs to be rebuilt. When rebuilding a Standby, it removes all of the Standby's databases and rebuilds them based on the Primary's database. In this process, if the backup file required for rebuilding does not exist in the Primary database, the backup is performed on the Primary, which can cause performance degradation.
MariaDB Procedure
RDS for MariaDB provides its own procedures for performing some of the features that are restricted from user accounts to provide user convenience.
tcrds_active_process
- Make inquiry of Process list for ACTIVE status, not Sleep status.
- Data output is displayed in order of longest performance time to shortest, and the query value (SQL) is displayed up to a hundred digits.
mariadb> CALL mysql.tcrds_active_process();tcrds_process_kill
- Forces to end a specific process.
- Process ID to end can be checked in information_schema.processlist, and the process information can be checked using the tcrds_active_process and tcrds_current_lock procedures.
mariadb> CALL mysql.tcrds_process_kill(processlist_id );tcrds_current_lock
- Check the processes currently waiting for a lock and the process information occupying the lock.
- (w) Process information that column information waits to obtain locks
- (B) Process information that column information occupies locks
- To force shutdown a process that occupies a lock, check the (B)PROCESS column and perform call tcrds_process_kill(process_id).
mariadb> CALL mysql.tcrds_current_lock();tcrds_repl_changemaster (prior to 8.4)
- Used to import external MariaDB DBs into NHN Cloud RDS using replication.
- Replication configuration of NHN Cloud RDS is done with Create replication of the console.
mariadb> CALL mysql. tcrds_repl_changemaster (master_instance_ip, master_instance_port, user_id_for_replication, password_for_replication_user, MASTER_LOG_FILE, MASTER_LOG_POS);- Explaining parameter
- master_instance_ip : IP of replication target (Master) server
- master_instance_port: MariaDB port on the replication target (Master) server
- user_id_for_replication: an account for replication to access MariaDB on the replication target (Master) server
- password_for_replication_user : Password of account for replication
- MASTER_LOG_FILE : Binary log file name of replication target (Master)
- MASTER_LOG_POS : Binary log file position of replication target (Master)
ex) call mysql.tcrds_repl_changemaster('10.162.1.1',10000,'db_repl','password','mysql-bin.000001',4);Caution
The account for replication must be created in MariaDB of the replication target (Master).
tcrds_repl_changesource (after 8.4)
- Used when importing an external MariaDB DB to NHN Cloud RDS using replication.
- Replication configuration for NHN Cloud RDS can be done through Create Replica in the console.
mariadb> CALL mysql.tcrds_repl_changesource (master_instance_ip, master_instance_port, user_id_for_replication, password_for_replication_user, SOURCE_LOG_FILE, SOURCE_LOG_POS);- Parameter Details
- master_instance_ip: IP of the replication target (Master) server
- master_instance_port: MariaDB port on the replication target (Master) server
- user_id_for_replication: Replication account to connect to MariaDB on the replication target (Master) server
- password_for_replication_user: account passowrd for replication
- SOURCE_LOG_FILE: Binary log file name of the replication target (Master)
- SOURCE_LOG_POS: binary log position of the replication target (Master)
ex) call mysql.tcrds_repl_changesource('10.162.1.1',10000,'db_repl','password','mysql-bin.000001',4);Caution
The replication account must be created in the replication target (Master) MariaDB.
tcrds_repl_init
- Reset MariaDB replication information.
mariadb> CALL mysql.tcrds_repl_init();tcrds_repl_slave_stop (before 8.4)
- Stop MariaDB replication.
mariadb> CALL mysql.tcrds_repl_slave_stop();tcrds_repl_replica_stop (after 8.4)
- Stop MariaDB replication.
mariadb> CALL mysql.tcrds_repl_replica_stop();tcrds_repl_slave_start (before 8.4)
- Start MariaDB replication.
mariadb> CALL mysql.tcrds_repl_slave_start();
tcrds_repl_replica_start (after 8.4)
- Start MariaDB replication.
mariadb> CALL mysql.tcrds_repl_replica_start();
tcrds_repl_skip_repl_error
- If you run the TCRDS_REPL_SKIP_REPL_ERROR procedure when the Duplicate Key error occurs, you can address the replica error.
- Before 8.4: perform SQL_SLAVE_SKIP_COUNTER=1.
- After 8.4: perform SQL_REPLICA_SKIP_COUNTER=1.
MariaDB error code 1062: 'Duplicate entry ? for key ?'
mariadb> CALL mysql.tcrds_repl_skip_repl_error();tcrds_repl_next_changemaster (before 8.4)
- Changes replication information to read the next binary log of master.
- When the following replication errors happens, run tcrds_repl_next_changemaster procedure to resolve the replication errors.
e.g. MariaDB error code 1236 (ER_MASTER_FATAL_ERROR_READING_BINLOG): Got fatal error from master when reading data from binary log
mariadb> CALL mysql.tcrds_repl_next_changemaster();tcrds_repl_next_changesource (after 8.4)
- Change the replication information so that you can read the next binary log log.
- If you run the TCRDS_REXT_CHANGESOURCE procedure when the following replication error occurs, you can issue the replication error.
e.g. MariaDB error code 1236 (ER_SOURCE_FATAL_ERROR_READING_BINLOG): Got fatal error from source when reading data from binary log
mariadb> CALL mysql.tcrds_repl_next_changesource();tcrds_innodb_monitor_reset
- A procedure that runs innodb_monitor_reset variables that reset the counter in Information_schema.INNODB_METRICS table to zero.
- Run the following query:
SET GLOBAL innodb_monitor_reset = '{counter-name|module_name|pattern|all}';. - innodb_monitor_enable, innodb_monitor_disable provides RDS parameter.
mariadb> CALL mysql.tcrds_innodb_monitor_reset('{counter-name|module_name|pattern|all}');ex) CALL mysql.tcrds_innodb_monitor_reset('dml_reads');
CALL mysql.tcrds_innodb_monitor_reset('module_dml');tcrds_innodb_monitor_reset_all
- A procedure to run innodb_monitor_reset_all variables to reset counter value.
- To use innodb_monitor_reset_all, the counter should be in disable state.
- Run the following query:
SET GLOBAL innodb_monitor_reset_all = '{counter-name|module_name|pattern|all}';.
mariadb> CALL mysql.tcrds_innodb_monitor_reset_all('{counter-name|module_name|pattern|all}');tcrds_foreign_key_checks
- A procedure that controls the
foreign_key_checksvariable that checks for foreign key constraints. - Run the following query:
SET GLOBAL foreign_key_checks ='ON|OFF';.
mariadb> CALL mysql.tcrds_foreign_key_checks('{0|1|'OFF'|'ON'}');Data Migration
- RDS can be exported as data to or imported from NHN Cloud RDS using mysqldump.
- The mysqldump utility is provided by default when MariaDB is installed.
Export using mysqldump
- Prepare and use an instance of NHN Cloud RDS.
- Check that the external instance on which you want to store the data to be exported, or the computer on which the local client is installed, has sufficient capacity.
- If you need to export data outside of NHN Cloud, create Floating IP and connect it to the RDS instance where you want to export the data.
- Export data externally using the mysqldump command below.
When exporting files
mysqldump -h{rds_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port} --single-transaction --routines --events --triggers --databases {database_name1, database_name2, ...} > {local_path_and_file_name}Exporting in mariadb db out of NHN Cloud RDS
mysqldump -h{rds_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port} --single-transaction --routines --events --triggers --databases {database_name1, database_name2, ...} | mysql -h{external_db_host} -u{external_db_id} -p{external_db_password} --port={external_db_port}Import by using mysqldump
- Prepare db outside NHN Cloud RDS to import data.
- Check that the NHN Cloud RDS instance that you import has sufficient capacity.
- Create a Floating IP to connect to the NHN Cloud RDS instance.
- Import data from outside using the mysqldump command below.
mysqldump -h{external_db_host} -u{external_db_id} -p{external_db_password} --port={external_db_port} --single-transaction --set-gtid-purged=off --routines --events --triggers --databases {database_name1, database_name2, ...} | mysql -h{rds_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port}When ERROR 1227 occurs during data importing
ERROR 1227occurs when a stored object (trigger, view, function, or event) in the mysqldump file has DEFINER definition.- To resolve the error, delete the
DEFINERpart of the mysqldump file and proceed.
When ERROR 1418 occurs during data importing
ERROR 1418occurs when the function declaration in the mysqldump file does not contain NO SQL, READS SQL DATA, or DETERMINISTIC and binary logging is enabled.- For detailed information, refer to The Binary Log MySQL document.
- To resolve the error, Parameter value of
log_bin_trust_function_creatorsof DB instance to which you want to apply mysqldump file should be changed to1.
Export by using replication
- Replication allows you export data from NHN Cloud RDS to external DB.
- The external db version has to be the same as or later than the version of NHN Cloud RDS.
- Prepare an instance of NHN Cloud RDS Primary or Read Replica to export data.
- Create Floating IP to connect to NHN Cloud RDS instances to export data.
- Use the command below to export data from the NHN Cloud RDS instance to a file.
- When exporting from Primary RDS instance.
mysqldump -h{rds_master_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port} --single-transaction --master-data=2 --routines --events --triggers --databases {database_name1, database_name2, ...} > {local_path_and_file_name}- When exporting from Read Replica RDS.
mysqldump -h{rds_read_only_slave_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port} --single-transaction --dump-slave=2 --routines --events --triggers --databases {database_name1, database_name2, ...} > {local_path_and_file_name}- Open the backed up file and record the MASTER_LOG_FILE and MASTER_LOG_POS written in the annotation separately.
- Check that the external local client or computer on which db is installed has sufficient capacity to back up data from the NHN Cloud RDS instance.
- Add the following options to my.cnf (for winodws my.ini) file in external DB.
- For server-id, enter a value different from the server-id of the parameter entry for the NHN Cloud RDS instance.
...
[mysqld]
...
server-id={server_id}
replicate-ignore-db=rds_maintenance
...- Restart external DB.
- Enter the backed up file into an external DB using the command below.
mysql -h{external_db_host} -u{external_db_id} -p{external_db_password} --port={external_db_port} < {local_path_and_file_name}- Create an account for replication on the NHN Cloud RDS instance.
- Before setting up a new replication, run the query below to initialize existing replication information that may exist. When you run RESET SLAVE, the existing replication information is initialized.
Before 8.4
STOP SLAVE;

RESET SLAVE;
After 8.4
STOP REPLICA;

RESET REPLICA;- Run the query on the external DB as shown below, using the account information to be used for replication and the MASTER_LOG_FILE and MASTER_LOG_POS that recorded earlier.
Before 8.4
CHANGE MASTER TO master_host = '{rds_master_instance_floating_ip}', master_user='{user_id_for_replication}', master_password='{password_forreplication_user}', master_port ={rds_master_instance_port}, master_log_file ='{MASTER_LOG_FILE}', master_log_pos = {MASTER_LOG_POS};

START SLAVE;
After 8.4
CHANGE REPLICATION SOURCE TO source_host = '{rds_master_instance_floating_ip}', source_user='{user_id_for_replication}', source_password='{password_forreplication_user}', source_port ={rds_master_instance_port}, source_log_file ='{SOURCE_LOG_FILE}', source_log_pos = {SOURCE_LOG_POS};

START REPLICA;- If the source data of the external DB and the NHN Cloud RDS instance are identical, use the STOP SLAVE command to the external DB to terminate the replication
Import with Replication
- You can import external DBs into NHN Cloud RDS using replication.
- NHN Cloud RDS version has to be the same as or later than the external DB version.
- Connect the data to an external MariaDB instance to which it is exported.
- Use the command below to back up data from an external MariaDB instance.
- To import data from external MariaDB instance (master)
mysqldump -h{master_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port} --single-transaction --master-data=2 --routines --events --triggers --databases {database_name1, database_name2, ...} > {local_path_and_file_name}- To import data from external MySQL instance (slave)
mysqldump -h{slave_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port} --single-transaction --dump-slave=2 --routines --events --triggers --databases {database_name1, database_name2, ...} > {local_path_and_file_name}- Open the backup file to record MASTER_LOG_FILE and MASTER_LOG_POS from the footnote.
- Verify that there is enough capacity on the client or computer to back up data from NHN Cloud RDS instance.
- Add the following option to the my.cnf (or my.ini for Windows) file of the external database.
- Put a different value for Server ID, from the Server ID of parameter of NHN Cloud RDS Instance.
...
[mysqld]
...
server-id={server_id}
replicate-ignore-db=rds_maintenance
...- Restart external DB.
- As importing over an external network can take a long time,
- We recommend that you create an internal NHN Cloud Image, copy the backup file, and import it into NHN Cloud.
- Enter the backed up file into NHN Cloud RDS with the following command.
- Replication configuration does not support DNS, so convert to IP and run.
mysql -h{rds_master_instance_floating_ip} -u{db_id} -p{db_password} --port={db_port} < {local_path_and_file_name}- Create an account for replication on an external MariaDB instance.
Before 8.4
mariadb> CREATE USER 'user_id_for_replication'@'{external_db_host}' IDENTIFIED BY '<password_forreplication_user>';
mariadb> GRANT REPLICATION CLIENT, REPLICATION SLAVE ON *.* TO 'user_id_for_replication'@'{external_db_host}';
After 8.4
mariadb> CREATE USER 'user_id_for_replication'@'{external_db_host}' IDENTIFIED BY '<password_forreplication_user>';
mariadb> GRANT REPLICATION CLIENT, REPLICATION REPLICA ON *.* TO 'user_id_for_replication'@'{external_db_host}';- Run a query on NHN Cloud RDS as follows, using the account information to be used for replication and the MASTER_LOG_FILE and MASTER_LOG_POS that recorded earlier.
Before 8.4
mariadb> call mysql.tcrds_repl_changemaster ('rds_master_instance_floating_ip',rds_master_instance_port,'user_id_for_replication','password_forreplication_user','MASTER_LOG_FILE',MASTER_LOG_POS );After 8.4
mariadb> call mysql.tcrds_repl_changesource ('rds_master_instance_floating_ip',rds_master_instance_port,'user_id_for_replication','password_forreplication_user','SOURCE_LOG_FILE',SOURCE_LOG_POS );- To start replication, execute the following procedure.
Before 8.4
mariadb> call mysql.tcrds_repl_slave_start;After 8.4
mariadb> call mysql.tcrds_repl_replica_start;- When original data of NHN Cloud RDS instance become same as the external database, close replication by using the following command:
mariadb> call mysql.tcrds_repl_init();Appendix
Appendix 1. DB Instance Migration Guide for Hypervisor Maintenance
NHN Cloud periodically updates the hypervisor software of the DB instance to improve security and stability. DB instances running on a hypervisor that requires maintenance must be migrated to the hypervisor where maintenance has been completed.
You can start migrating DB instances from the NHN Cloud console. When you select a specific DB instance according to the parameter and migrate it, if the associated DB instance (e.g., Read Replica instance) is also an inspection target, it proceeds with the migration together. Follow the guide below to use the migration feature on the console. Navigate to the project where the specified DB instance to be checked.
1. Check the DB instance that requires maintenance.
Check the DB instances subject to maintenance in the list on the DB Instance tab. You can check for hypervisor migration tasks by clicking Required in the Maintenance menu, or by visiting the Maintenance tab in the DB Instance Details. Click View on the hypervisor migration maintenance task to view detailed information about the hypervisor migration.
2. Make sure you close any running applications on the DB instance.
Take appropriate measures to avoid affecting services connected to the DB. If it is inevitable to affect the service, please contact NHN Cloud Customer Support, and we will guide you on appropriate measures.
3. You can apply migration to DB instances targeted for maintenance.
Select the DB instance to migrate, and then click Apply Immediately to perform the hypervisor migration right away. Click Apply in the Next Maintenance Duration to schedule the hypervisor migration for your preferred maintenance duration.
4. Wait for the DB instance migration to finish.
If the DB instance state does not change, do 'refresh'. No operations can be performed on the DB instance while migration is in progress. If the DB instance migration is not completed normally, it is automatically reported to the administrator, and NHN Cloud will contact you.
Appendix 2. Configuration guide for using Federated Storage Engine with RDS
When using Federated Storage Engine, make sure you consider the following.
For configuration using RDS as a local node
- Make sure you need to allow the outbound direction to remote nodes.
- You can add rules from DB security group.
- Refer to DB Security Group for more information.
- When using a configuration that adds Read Replica to RDS that serves as a local node, you need to specify a federated table in replicate-ignore-table of parameter.
- When you configure Read Replica, the federated table is also replicated, allowing the Primary and Read Replica to look at the remote node together.
- In this case, the data input performed on the Primary is performed on the remote node according to the federated setting, and the same input is performed on the Read Replica, which may lead to stop replication due to duplicate key errors.
- Make sure you need to configure the settings of replicate-ignore-table so that Read Only Save does not replicate a federated table.
For configuration using RDS as a remote node
- Make sure you need to allow the inbound direction to local nodes.
- You can add rules from DB security group.
- Refer to DB Security Group for more information.
Appendix 3. Security Patch
NHN Cloud periodically manages security vulnerabilities (CVEs) found in the operating systems of DB instances and provides security patch maintenance tasks for affected DB instances. Security patches work by applying the latest security updates that resolve the current vulnerabilities of DB instances. Follow the guide below to use the security patch feature in the console. Navigate to the project that contains the DB instances designated as security patch targets.
1. Check the DB instances targeted for security patching.
You can check whether a security patch maintenance task exists by clicking Required or Available under Maintenance, or by checking the Maintenance tab in DB Instance Details.
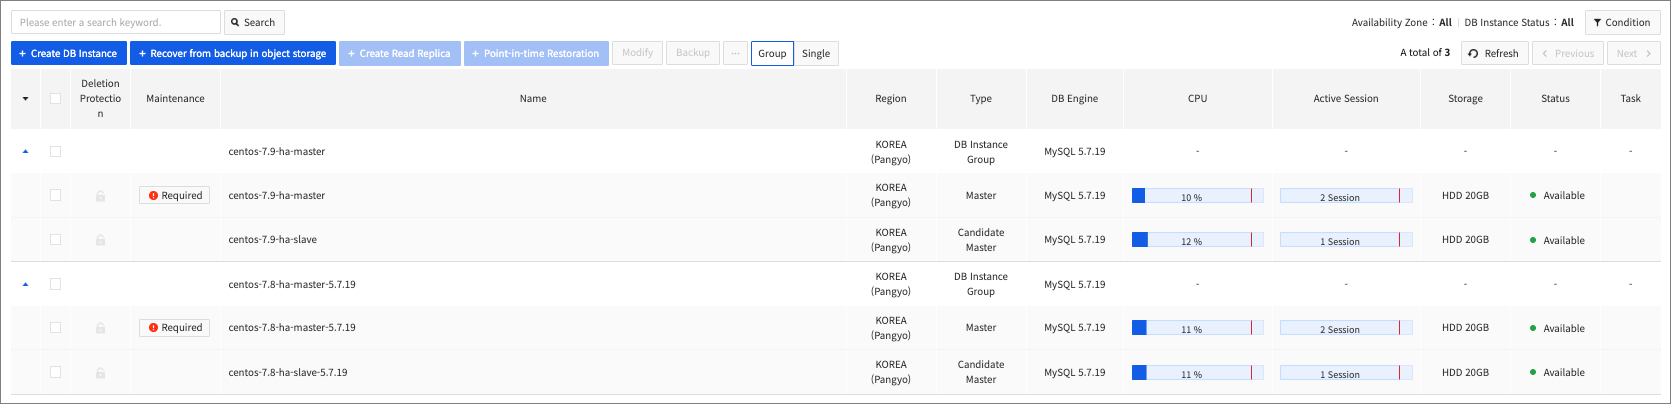
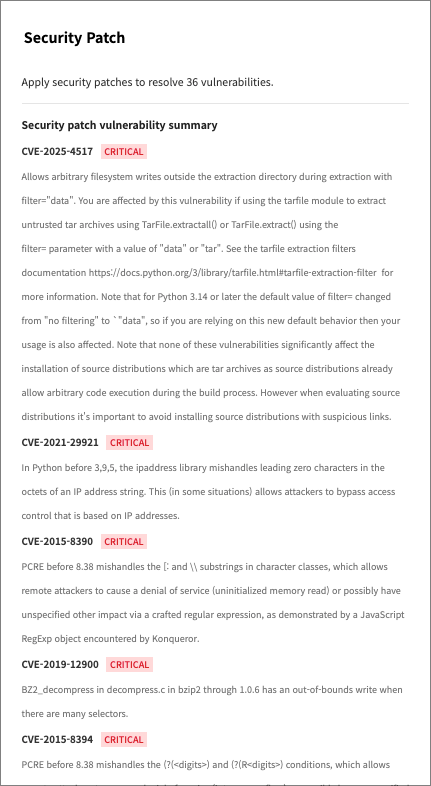
❶ Click the View button for the security patch maintenance task. ❷ You can check information on security vulnerabilities applicable to the current DB image.
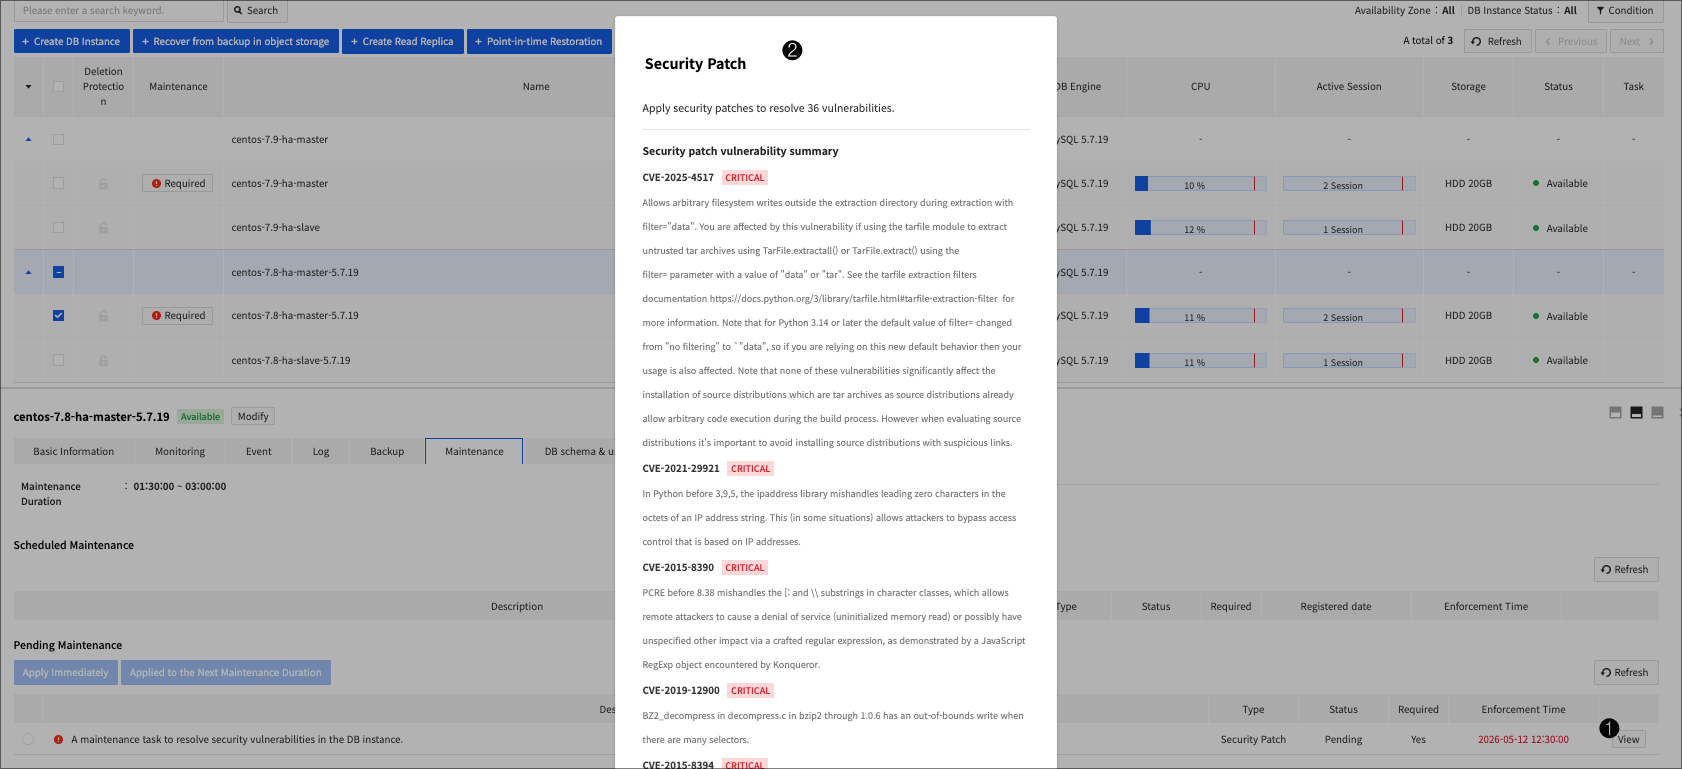
You can check information on security vulnerabilities that can be resolved by proceeding with the security patch.
Note
Vulnerability severity is classified as CRITICAL, HIGH, MEDIUM, or LOW.
2. Check the applications connected to the DB instances targeted for security patching.
Security patching may cause a brief service interruption on the DB instance. For high-availability DB instances, service interruptions can be minimized through failover. For single DB instances, the security patch is applied through a restart. Take appropriate measures to avoid affecting services connected to the DB.
3. Select when to apply the security patch.
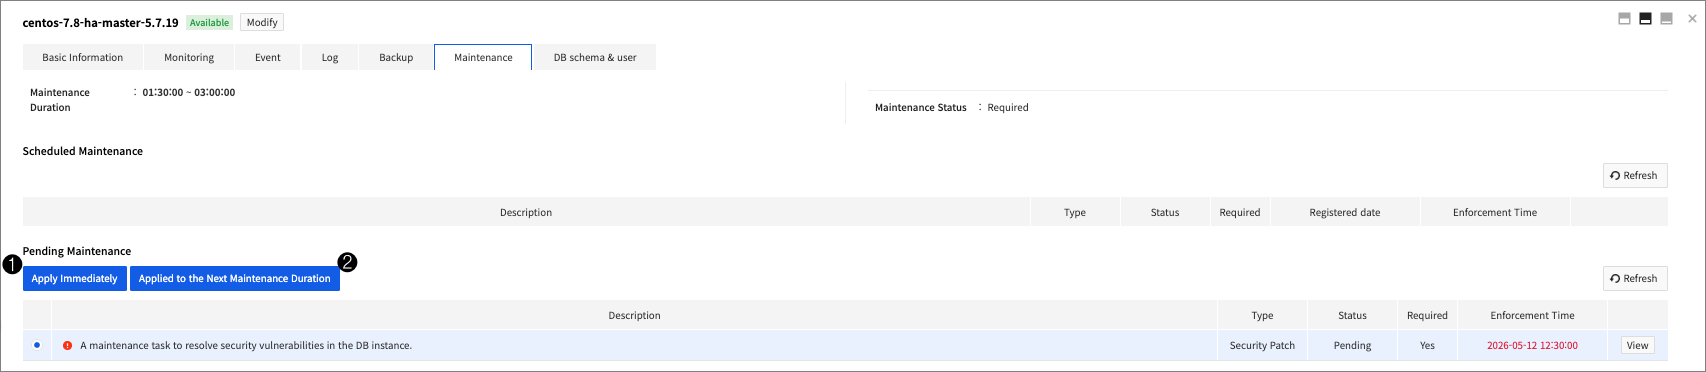
❶ Click Apply immediately to apply the security patch right away. ❷ Click Apply at next maintenance window to apply the security patch during the scheduled maintenance window.
When applying to a high-availability DB instance, the following options can also be selected:
- Run pre-backup: Automatically runs a backup before performing the security patch.
- Select failover method: Selects whether to use online failover or manual failover.
- Wait for replication lag: Waits until replication lag is resolved before proceeding with the security patch.
- Read Only mode: Uses read-only mode while the security patch is being performed.
4. Wait until the security patch is complete.
If the DB instance status does not change, refresh the page.
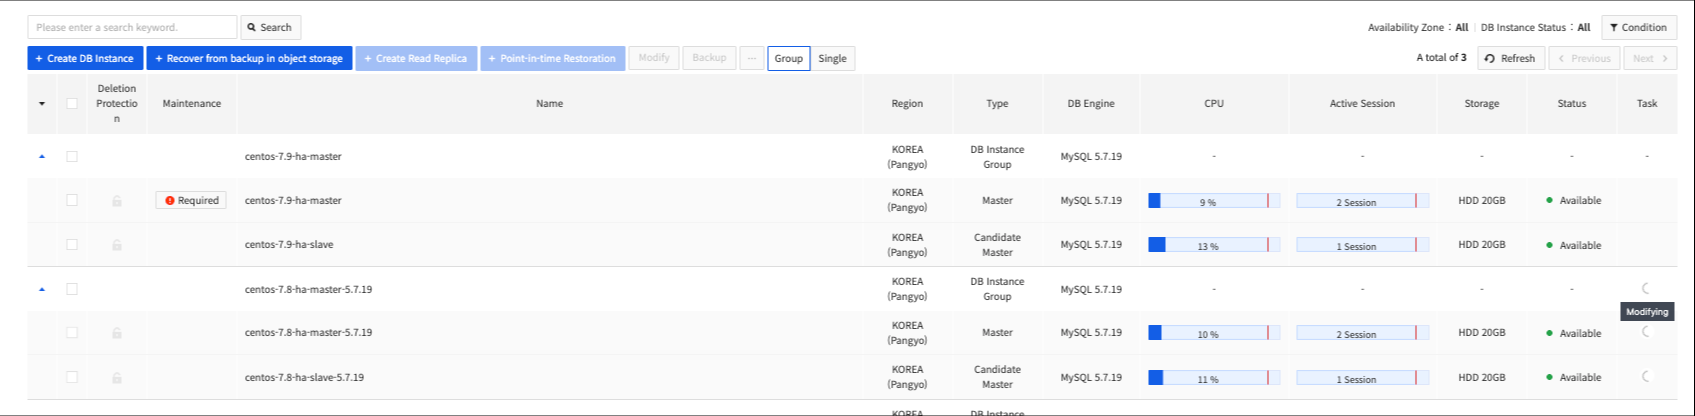
No operations can be performed while a security patch is in progress on a DB instance. If the security patch does not complete successfully, it is automatically retried. If it fails repeatedly, the issue is reported to an administrator and NHN Cloud will contact you separately.
Table of Contents
- Database > RDS for MariaDB > DB Instance
- DB Instance
- Create DB Instance
- Availability Zone
- DB Engine
- DB Instance Type
- Data Storage
- High Availability
- Network
- Floating IP
- Parameter group
- DB Security Group
- Backup
- Maintenance
- Default Notification
- Deletion Protection
- DB Instance List
- DB Instance Group Details
- DB Schema and Users
- Update DB Instance Group
- DB Schema & Direct User Control
- DB Instance Details
- Access Information
- Virtual IP
- Log
- Maintenance
- Modify DB instance
- Upgrade DB instance operating system
- Delete DB Instance
- Backup
- Restoration
- Secure Capacity
- Expand Storage Size
- Auto Scale Storage
- Apply parameter group changes
- Recover from backup in Object Storage
- Export backup files to Object Storage after backup
- Read Replica
- Create Read Replica
- Promote Read Replica
- Force Promotion of Read Replicas
- Stop Replication of Read Replicas
- Rebuild Read Replica
- Restart DB instance
- DB instance force restart
- Change Deletion Protection Settings
- High Availability DB Instances
- Failure Detection
- Automatic Failover
- Failed Over Primary
- Recover Failed Over Primary
- Rebuild Failed Over Primary
- Separate Failed Over Primary
- Manual Failover
- High availability suspended
- Rebuild Standby
- MariaDB Procedure
- tcrds_active_process
- tcrds_process_kill
- tcrds_current_lock
- tcrds_repl_changemaster (prior to 8.4)
- tcrds_repl_changesource (after 8.4)
- tcrds_repl_init
- tcrds_repl_slave_stop (before 8.4)
- tcrds_repl_replica_stop (after 8.4)
- tcrds_repl_slave_start (before 8.4)
- tcrds_repl_replica_start (after 8.4)
- tcrds_repl_skip_repl_error
- tcrds_repl_next_changemaster (before 8.4)
- tcrds_repl_next_changesource (after 8.4)
- tcrds_innodb_monitor_reset
- tcrds_innodb_monitor_reset_all
- tcrds_foreign_key_checks
- Data Migration
- Export using mysqldump
- Import by using mysqldump
- Export by using replication
- Import with Replication
- Appendix
- Appendix 1. DB Instance Migration Guide for Hypervisor Maintenance
- Appendix 2. Configuration guide for using Federated Storage Engine with RDS
- Appendix 3. Security Patch